42x Faster Prompt Lookup Drafting in llama.cpp
[homepage] [github] [twitter]
<sub>This article was originally published on 2026-09-26.</sub>TL;DR I make drafting for prompt lookup decoding in llama.cpp up to 42x faster while using up to 2.6x less memory through a set of simple performance optimizations largely based on the work of Daniel Lemire and Martin Ankerl.
Update: Daniel Lemire sent in a PR that makes prompt lookup drafting upto 4.2x faster on top of my original optimizations. His work makes the overall speedup upto 140x. I discuss more below.
Many popular inference engines including llama.cpp and vllm, and machine learning libraries such as hugging face's transformers library, support prompt lookup decoding (also called n-gram speculation) for faster token generation. Prompt lookup decoding is technically a special case of speculative decoding that uses a really stupid draft model, an n-gram model. When prompt lookup decoding is used, the inference engine drafts the next $k$ tokens using the following rule.
Let $x_1, \ldots, x_t$ be the current tokens of a model. An n-gram is a sequence of $n$ consecutive tokens. For example, a 3-gram would be $(x_1, x_2, x_3)$ or $(x_2, x_3, x_4)$ or, in general, $(x_i, x_{i+1}, x_{i+2})$ for any $i \in {1, \ldots, t-2}$. Now an n-gram model is a probabilistic model that predicts the next token based on the previous $n - 1$ tokens. The idea is extremely simple. You first select some corpus of text and parse it into n-grams. You then count the frequency of each n-gram. When your n-gram model needs to predict the next token after a sequence of $n-1$ tokens, you make the n-gram model select the token that most frequently follows that sequence of $n-1$ tokens in your corpus.
llama.cpp maintains three types of n-gram caches. Let $\eta$ be any n-gram and $y$ be any token. An n-gram cache is a data structure that stores $c(\eta, y)$, i.e., the count of how many times the token $y$ follows the n-gram $\eta$, for all n-grams $\eta$ and all tokens $y$ in a given corpus and vocabulary. The three n-gram caches used by llama.cpp are the context cache, the dynamic cache, and the static cache.
llama.cpp's context cache stores n-grams of sizes 1 to 4 for the current tokens $x_1, \ldots, x_t$ being
processed by the model. The context cache is updated as the model generates new tokens. The
dynamic cache stores the counts of n-grams from previous runs of the model, e.g., any earlier
conversations. Finally, the static cache stores n-grams of size 2 from a static text corpus, built
with `llama-lookup-create`.
I denote the context, dynamic, and static caches by $c_{\text{ctx}}$, $c_{\text{dyn}}$, and $c_{\text{st}}$, respectively.
llama.cpp drafts a new token using its n-gram caches in the following way. Let $X_n = (x_{t-n+1}, \ldots, x_t)$ be the previous $n$ tokens processed by the model. For all tokens $y$ in the vocabulary, llama.cpp computes a score using the formula
$s_n^{f}(y) = f(X_n, y) \cdot w(y) \,\, \text{where} \,\, w(y) = \begin{cases} 100 \, c_{\text{st}}(X_2, y) & \text{if $c_{\text{st}}(X_2, y) > 0$} \ 1 & \text{otherwise} \end{cases}$ where $f$ is either the context cache $c_{\text{ctx}}$ or the dynamic cache $c_{\text{dyn}}$. Note that the weight $w(y)$ favors tokens that also agree with the static cache. Without a static cache, $w(y) = 1$ for every token. For each $n$, llama.cpp takes the highest-scoring token $y^* = \arg\max_y s_n^{f}(y)$. Let $F(X_n) = \sum_y f(X_n, y)$ be the number of times $X_n$ appeared with a token after it. llama.cpp drafts $y^*$ based on two configurable thresholds $a_n$ and $p_n$ in the following way.
$F(X_n) \ge a_n \,\, \text{and} \,\, f(X_n, y^*) \ge p_n \, F(X_n)$ In other words, $X_n$ must appear at least $a_n$ times and the token $y^$ must have followed $X_n$ in at least a fraction $p_n$ of those occurrences for $y^$ to be accepted as a draft token. As of release b11182 of llama.cpp, the thresholds are hard-coded as follows. For the context cache, $(a_1, a_2, a_3, a_4) = (2, 2, 1, 1)$ and $(p_1, p_2, p_3, p_4) = (0.66, 0.5, 0.5, 0.5)$. For the dynamic cache, $(a_1, a_2, a_3, a_4) = (4, 3, 2, 2)$ and $(p_1, p_2, p_3, p_4) = (0.75, 0.66, 0.66, 0.66)$. llama.cpp tries $n = 4, 3, 2, 1$ and drafts the first $y^*$ that passes the conditions above. It first scores with $c_{\text{ctx}}$. It scores with $c_{\text{dyn}}$ only when no candidate from $c_{\text{ctx}}$ passes for any $n$. If no candidate from $c_{\text{dyn}}$ passes either, llama.cpp falls back to relying only on the static cache (as opposed to only using it to reweight candidates in the other caches). As a side note, the static cache's thresholds in llama.cpp are the same values as the context cache's thresholds for the corresponding $n$, i.e., $n = 2$. Let $C_{\text{st}}(X_2) = \sum_y c_{\text{st}}(X_2, y)$. llama.cpp takes the token $y$ with the largest $c_{\text{st}}(X_2, y)$ and drafts it when $C_{\text{st}}(X_2) \ge a_2 = 2$ and $c_{\text{st}}(X_2, y) \ge p_2 \, C_{\text{st}}(X_2) = 0.5 \, C_{\text{st}}(X_2)$. If the static cache also fails, llama.cpp does not draft the next token.
llama.cpp's repository includes an example for prompt lookup decoding
here.
It includes two tools I use: `llama-lookup-create` for building a static cache from a corpus
and `llama-lookup-stats` for benchmarking prompt lookup decoding.
`llama-lookup-stats` essentially reads a file and treats the file's tokens
as the output of a model. It runs the drafting loop from llama.cpp over the simulated
"model output" (i.e. the file) and records how many drafted tokens match the file, the time it took
to draft the tokens, and the time it took to load the static ngram cache.

I build the static caches using `llama-lookup-create` with
WikiText-103 and then I
replay the WikiText-103 test text through `llama-lookup-stats`. I borrowed
this evaluation method from the
PR
by @JohannesGaessler that added
the static n-gram cache to llama.cpp. Note that since I am not making any
algorithmic modifications to how prompt lookup decoding works in llama.cpp, the dataset
mainly matters for the acceptance rate, which my changes leave unchanged. Just to be safe, I make
sure my changes still have almost identical acceptance rates to the original implementation.
The important metrics here that actually change are 1) latency
per drafted token, 2) the load time of the static cache, and 3) the memory used by the static cache.
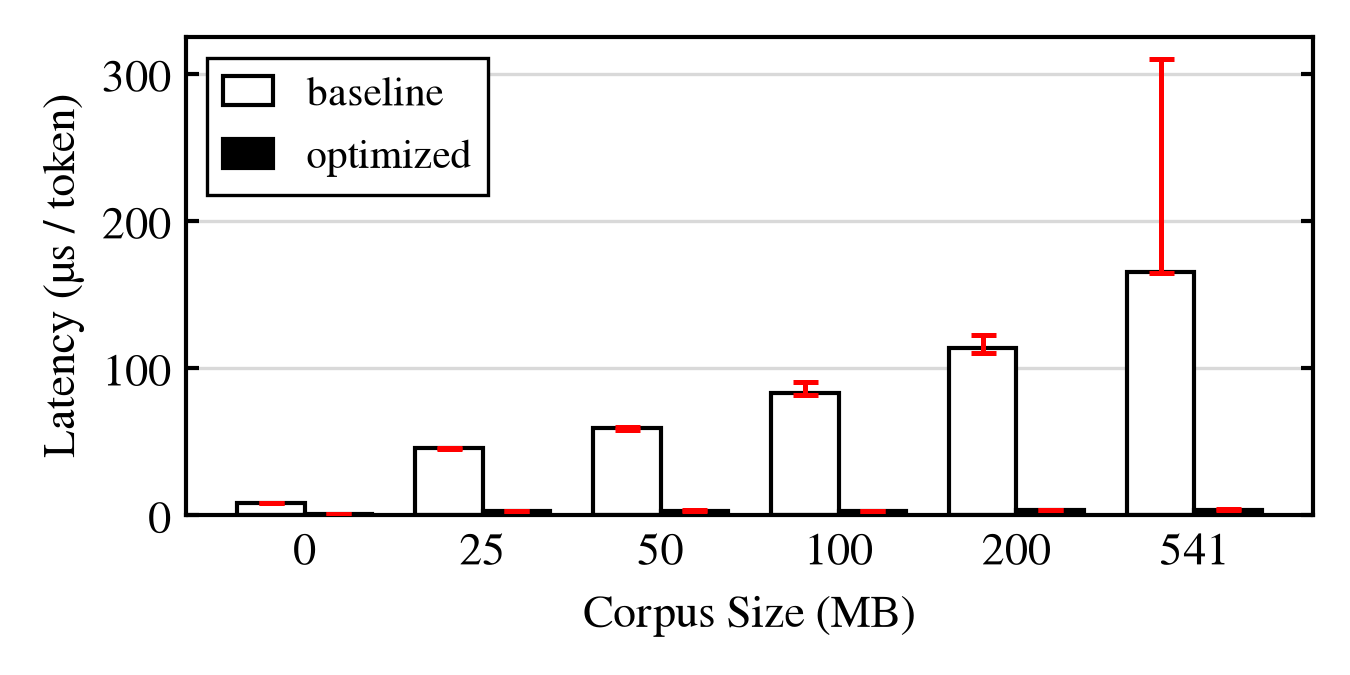
I also wanted to observe how the performance changes with different corpus sizes for the static n-gram cache. So in addition to evaluating the full corpus of WikiText-103, which is about 541 MB, I also build static caches from the first 25, 50, 100, and 200 MB of the WikiText-103 training text. A corpus size of 0 in the figures means I run without a static cache, which measures the context and dynamic caches alone. For all the results in this work, I am reporting the median of 3 runs with the error bars displaying the min and the max value for the runs. Following the llama.cpp PR I linked in the previous paragraph, I also benchmark assuming a model context side of 4096 tokens. I run all my experiments on an Apple M4 Pro with 14 cores and 48 GB of memory. All of my code and results are in this repository.
The n-gram caches in llama.cpp are currently implemented as nested std::unordered_maps. An outer
map sends each n-gram to an inner map of the tokens that follow it and their counts.
This one is almost more of a bug fix than an optimization. I found that the inner maps were
being copied unnecessarily in multiple places on every drafting step.
I created this simple PR
to read them by reference instead.
This immediately made drafting 4.5x to 25.6x faster depending on the size of the
corpus (see figure below). The latency is the average time spent
drafting per drafted token.
llama.cpp implements an n-gram cache as a map of maps.
typedef std::unordered_map<common_ngram, common_ngram_cache_part,
common_ngram_hash_function> common_ngram_cache;common_ngram_cache, maps each n-gram to an inner map. The inner
map, a common_ngram_cache_part, map stores the counts of each token in the vocabulary
that follows the given n-gram. As an example, if
"of the" is followed by "city" 6 times, "war" 3 times, and "year" once, the n-gram cache looks like this.
common_ngram_cache
  ("of", "the")  ->  common_ngram_cache_part { "city": 6, "war": 3, "year": 1 }
  ("in", "the")  ->  common_ngram_cache_part { ... }
  ....
llama.cpp currently implements both the outer and inner maps as an std::unordered_map.
However, the standard library's implementation of std::unordered_map is
famously slow
because it uses chaining for collision resolution with linked lists as its buckets
which is cache unfriendly. There are many great alternatives here such as Google's
Swiss Tables (which
were also recently added to Golang)
and Martin Ankerl's unordered_dense maps.
I decided to go with ankerl::unordered_dense because 1) I really like its design and
performance, and 2) it is less of an annoyance than trying
to add all of abseil as a dependency to llama.cpp.
My change is in this PR. This makes 1) loading the static n-gram cache 1.41x to 1.65x faster depending on the size of the corpus,
drafting a new token 1.02x to 1.13x faster, and 3) the static cache use 1.07x to 1.11x
less memory. See the figures below. Note that I use the
segmented_mapvariant ofankerl::unordered_denseinstead of the defaultmapvariant. The defaultmapvariant keeps all entries in one vector that doubles as it fills. When I experimented with themapvariant on the full 541 MB corpus, the final doubling of the vectors caused the static cache to use 1.16x more memory than the baseline. Note that the baseline here is my previous PR where I removed the unnecessary map copying. Thesegmented_mapvariant avoids this issue by growing the map in segments of 4096 bytes allowing for lower peak memory usage.
In the previous section, I only replaced the outer map with an ankerl::unordered_dense::segmented_map.
The inner map is still a sad old std::unordered_map. Notice that most
n-grams have very few followers which makes having a std::unordered_map
or any kind of hash map for each inner map quite wasteful in terms of memory. Doing
some street fighting math on the static cache created from WikiText-103, you can
get the following CDF.
The important observation is that since 64% of the 2-grams used for drafting the static n-gram cache
have only one follower, simply using an `std::vector` is much more memory efficient than
maintaining hash maps for the inner map. The distribution is pretty heavy tailed though. A few frequent
2-grams are following by thousands of distinct tokens from the vocabulary which is why the figure
goes all the way to $10^4$ before the tail tapers off to $\to 1$. So simply using a regular
`std::vector` would blow up the search latency for the n-grams at the tail. So
I used a sorted `std::vector` instead to keep the search still $\mathcal{O}(\log n)$ for the n-grams at the tail.
My first version simply used std::lower_bound with the sorted std::vector.
However, this approach slightly reduced the drafting speed making it only 0.89x as fast as
the baseline (the baseline being the previous optimization where I replaced the outer map with an
ankerl::unordered_dense::segmented_map). Most of the extra time goes into searching
the followers of frequent 2-grams, which can have thousands of entries. The loop of
std::lower_bound in libc++, simplified to our vector of (token, count) pairs, looks like this.
const value_type * first = pairs;
size_t len = n;
while (len != 0) {                 // the loop ends when len reaches 0
    const size_t half = len / 2;
    const value_type * mid = first + half;
    if (mid->first < token) {      // compares against an entry read from memory
        first = mid + 1;
        len -= half + 1;           // the new len depends on that entry
    } else {
        len = half;
    }
}
return first - pairs;
The remaining length len depends on the result of each comparison, and so does the number
of iterations. A search over 8 entries takes 3 or 4 iterations depending on the token. The CPU cannot
evaluate len != 0 until the entry of the current iteration arrives from memory, which is often a
cache miss for a vector with thousands of entries. My version separates the length from the comparison.
const value_type * base = pairs;
while (n > 1) {                    // the loop ends when n reaches 1
    const size_t half = n / 2;
    base = base[half].first < token ? base + half : base;   // only base depends on the entry
    n -= half;                     // n does not depend on any entry
}
return (base - pairs) + (base->first < token);
Here n shrinks by the same amount whatever the comparison returns. A search over 8 entries
always takes 3 iterations, with n going from 8 to 4 to 2 to 1. The CPU can evaluate
n > 1 without waiting for any entry, so it can move on to the search for the next candidate token
while the reads of the current search are still in flight.
My change is in this PR. Compared to the flat hash map, it makes drafting 2.09x faster without a static cache and 1.19x to 1.25x faster when a static cache is used. The PR also reduces by peak memory by as much as 1.97x. Loading the static cache takes about the same time.
Daniel Lemire recently published an optimized implementation of an immutable map from strings to 64-bit integers called constmap which is built on top of binary fuse filters.
Since llama.cpp never changes the static cache after loading it, this is a perfect use case for a constmap. I replaced the outer map of the static cache with a verified constmap. My implementation packs the 2-grams in the static n-gram cache into a contiguous array of (token, count) pairs. Using my earlier example (if "of the" is followed by "city" 6 times, "war" 3 times, and "year" once), the constmap stores the following.
pairs
  ...
  [1000]  ("city", 6)
  [1001]  ("war", 3)
  [1002]  ("year", 1)
  ...
constmap
  ("of", "the")  ->  (1000, 3)
  ("in", "the")  ->  ...
The followers of ("of", "the") start at position 1000 of the array. There are 3 of them. The constmap
stores the position 1000 and the count 3 together as one 64-bit value. The position takes the high 40 bits
of the value and the count takes the low 24 bits. The static cache file stores a small header, the array of pairs, and the
serialized constmap one after another. Loading reads the whole file into one buffer and opens the constmap inside that buffer with
fcm_verified_constmap_view. A lookup queries the constmap once and returns a pointer into the
array and the number of pairs.
common_ngram_cache_static_part common_ngram_cache_static_find(
        const common_ngram_cache_static & nc_static,
        const common_ngram & ngram) {
    const char * key = reinterpret_cast<const char *>(ngram.tokens);
    const uint64_t value = fcm_verified_constmap_lookup(
        nc_static.map.get(), key, STATIC_KEY_SIZE);
    if (value == FCM_NOT_FOUND) {
        return {};
    }
    const uint64_t position = value >> STATIC_LEN_BITS;
    const size_t   count    = value & STATIC_LEN_MASK;
    return { nc_static.entries + position, count };
}
Since the pairs themselves, e.g. ("city", 6), ("war", 3), ("year", 1), have the same layout as the sorted vectors of the previous section, the implementation still uses fixed-length binary search to find the count of a candidate token.
My change is in this PR. Compared to the sorted vectors, it makes loading the static cache 6.32x to 16.12x faster, from 3.76 s to 0.23 s with the 541 MB corpus. The static cache now takes about as much memory as its file, 463 MB for a 467 MB file. Peak memory drops by up to 1.30x, from 1.71 GB to 1.31 GB with the 541 MB corpus. Drafting with a static cache is 1.06x to 1.20x faster. The acceptance rate is identical to the sorted vectors on every corpus.
Daniel Lemire sent in this PR as an additional optimization. llama.cpp currently computes the score for all candidate tokens for a given n-gram first and then checks whether they meet the hardcoded thresholds $a_n$ and $p_n$ I mentioned earlier. Lemire's insight is to, instead, first check whether the most frequent follower of the n-gram can pass the threshold $p_n$. If the most frequent follower fails, the other candidate tokens will also fail, so we can skip computing their scores. Lemire also first checks if the n-gram's total count reaches $a_n$. If it doesn't, we can skip computing the scores for all candidate tokens. His change made drafting up to 4.2x faster with a static cache and up to 1.9x faster when there is no static cache on top of my optimizations.
If you would like to cite this work, please use the following bibtex. Thank you.
@misc{tirmazi2026promptlookup,
  author       = {Hayder Tirmazi},
  title        = {42x Faster Prompt Lookup Drafting in {llama.cpp}},
  year         = {2026},
  month        = sep,
  howpublished = {\url{https://jadidbourbaki.github.io/blog/prompt-lookup-llama-cpp/}}
}