We're excited to have worked with Meta Superintelligence Labs to bring Muse Spark Open to vLLM on day 0. Muse Spark Open is an open-weight sparse mixture-of-experts (MoE) model, built for long-horizon agentic coding workflows. It is the most capable US open-weights model to date and it is the model Muse Glimmer 30B was distilled from.
Highlights
- Architecture: 816B total parameters, 42B active per token with a 1M context window.
- Quantization: Meta released the model in both BF16 and NVFP4. MXFP4 weights were released by AMD.
- Multimodal: Native image and video perception through the same Perception Encoder as Muse Glimmer, with additional audio support.
- Parallelism: Tensor Parallelism and Pipeline Parallelism on both Nvidia and AMD. EP, TEP, DEP and PD disaggregation on Nvidia. Initial support on TPU is also available.
- Speculative decoding: We have trained a DSpark draft model, supported on both CUDA and ROCm that accelerates the model performance, tested on the SPEED bench.
Usage
Prebuilt images are available for both vendors:
- Nvidia: vllm/vllm-openai:muse-spark-open
- AMD: vllm/vllm-openai-rocm:muse-spark-open
Note that the model will only be available at nightly PyPI wheel after the code (PR #61879) is reviewed and merged, which usually takes about a week.
# Rust frontend is recommended
export VLLM_USE_RUST_FRONTEND=1

vllm serve meta-models/Muse-Spark-Open-816B-A42B-NVFP4 \
    --tensor-parallel-size 8 \
    --enable-expert-parallel \
    --max-model-len 1048576 \
    --reasoning-parser muse \
    --tool-call-parser muse \
    --enable-auto-tool-choice \
    --speculative-config '{"method":"dspark","model": "Inferact/Muse-Spark-Open-DSpark","num_speculative_tokens":7,"draft_sample_method":"probabilistic","rejection_sample_method":"block","enable_adaptive_verification":true}'
To use this model with plain text:
  curl http://localhost:8000/v1/chat/completions \
    -H 'Content-Type: application/json' \
    -d '{
      "model": "meta-models/Muse-Spark-Open-816B-A42B-NVFP4",
      "messages": [{"role": "user", "content": "Refactor this module."}],
      "reasoning_effort": "xhigh"
    }'
For multimodal perception:
 curl http://localhost:8000/v1/chat/completions \
   -H 'Content-Type: application/json' \
   -d '{
     "model": "meta-models/Muse-Spark-Open-816B-A42B",
     "messages": [{"role": "user", "content": [
       {"type": "image_url", "image_url": {"url": "https://example.com/screenshot.png"}},
       {"type": "video_url", "video_url": {"url": "https://example.com/demo.mp4"}},
       {"type": "audio_url", "audio_url": {"url": "https://example.com/clip.wav"}},
       {"type": "text",      "text": "What is happening here, and when?"}
     ]}]
   }'
Implementation details
Model architecture
Figure 1: One of the 62 identical decoder layers. Every block is normalized before and after, x + post_norm(F(norm(x))). Open it full-screen.
Muse Spark Open is a mixture-of-experts model with 816B total parameters including the text decoder, plus a 2B vision encoder and a small audio encoder alongside it. The decoder has 62 layers, and every one of them is a mixture-of-experts layer. Here is where the weights sit:
| part | size |
|---|---|
| 256 experts per layer | 799 B |
| attention | 13.5 B |
| MoE latent projections | 4.2 B |
| embedding and output layer | 3.3 B |
| vision tower (separate) | 1.9 B |
The model architecture is similar to Muse Glimmer. For folks who haven't used Muse Glimmer. There are a few things in this model architecture worth a closer look.
Figure 2: Inside the attention block. Queries and keys are normalized before they meet, and each head's output is normalized before a learned gate scales it. Open it full-screen.
Sandwich normalization. Most decoders put one normalization layer before each block, giving x + F(norm(x)) Muse Spark Open, similar to Muse Glimmer, place one before and one after, like the two slices of a sandwich with the block sitting in between, giving x + post_norm(F(norm(x)))
Figure 3: The mixture-of-experts block. A shared squeeze halves each token from 8192 to 4096 before the experts and an expand restores 8192 after. Open it full-screen.
Latent MoE. Every mixture-of-experts (MoE) layer carries two extra matrices, shared by all 256 experts in that layer. The code calls them the pooler and unpooler, though neither is pooling in the usual sense, instead both are learned projections to squeeze and expand the dimensions. The pooler is an 8192 × 4096 matrix that halves each token's width before it reaches the experts; while the unpooler restores the full width afterwards. The experts therefore work entirely at 4096 rather than 8192, which effectively halved the number of parameters required in the two expert projection layers.
Figure 4: Which layers attend to what. 46 of the 62 layers keep a 2048-token window of KV and 16 keep every token, so the KV cache at 1M tokens is about a quarter of all-full attention. Open it full-screen.
Hybrid attention. Layers alternate between full attention and Sliding Window Attention (SWA) on a repeating cycle of 4 with three attending to a 2048-token window and the fourth looking at the whole context. The cycle is anchored to the end of the stack so the final layer is always a full attention layer. Across 62 layers, that gives 46 narrow layers and 16 wide ones where the narrow layers only hold recent KV. At 1M tokens, this brings the cache to just over ¼ of what all-full attention would need. This is what makes 1M context length affordable.
Vision Encoder. Muse Spark Open uses the same Perception Encoder as Muse Glimmer, a 2B parameter tower that reads images at their native resolution, rather than resizing them to a square. Videos run through the same encoder: frames are sampled at load time as a series of sampled video frames with timestamp tokenized in the prompt.
Audio Encoder. Audio is read as raw waveform at 24 kHz and Every 1920 samples, i.e. 80ms become one token through a series of transformations. The whole audio encoder is just 118M parameters. Note that the video's audio track is not processed. To give the model both the pictures and the sound of a clip, send the video and the extracted audio as two separate content parts in the same request.
DSpark
To accelerate Muse Spark Open inference on vLLM, we trained a speculator using DSpark, a speculative decoding algorithm that uses block diffusion to propose up to seven draft tokens in a single pass. Confidence-based scheduling helps sustain significant speedups even at large batch sizes, where speculative decoding traditionally offers diminishing returns, as shown in the results below.
Figure 5: Aggregate output throughput against per-user decode speed on 4 × NVIDIA GB300 (TP4), one point per concurrency level from c1 to c256. Hover a point for every series' values, or open it full-screen.
Our speculator also uses the Muse Spark Open sliding-window attention to keep drafting lightweight, even with a 1M-token context. Together, these choices make it well suited to production workloads spanning a wide range of batch sizes and context lengths.
To enable it, add this when the server starts:
--speculative-config '{"method":"dspark","model": "Inferact/Muse-Spark-Open-DSpark","num_speculative_tokens":7,"draft_sample_method":"probabilistic","rejection_sample_method":"block","enable_adaptive_verification":true}'Nvidia
Nvidia team improved Muse Spark Open inference across FlashInfer and vLLM through fused normalization, gating, and residual kernels; fused MoE finalization with tensor-parallel communication and RMSNorm; a new low-latency BF16 GEMM implementation and reduced compilation overhead; TEP pooler/unpooler sharding with fused MNNVL collectives; TF32 router GEMM fed by the norm's FP32 output; and improvements to data movement, hardware support, and runtime reliability.
AMD
Thanks to the AMD team, we have also supported the model on AMD Instinct™ MI355X GPUs, in both FP8 and MXFP4 quantized formats, providing improved inference performance and deployment efficiency. Note that ROCm currently supports both Tensor-Parallel and Pipeline-Parallelism.
TPU
We have added support for Muse Spark Open on TPU on top of TorchTPU. Please contact us or Google for code access. We have also built megakernels for Muse Spark Open. With DSpark speculative decoding (acceptance length = 6), they reach over 650 tokens/sec on 4 TPU v7 chips and over 960 tokens/sec on 8 chips. Without speculative decoding, they still deliver over 270 and 350 tokens/sec, respectively.
Reinforcement learning in vLLM
vLLM also supports LoRA RL on Muse Spark Open from day 0, serving as the rollout engine with Verl FSDP2 as the trainer. vLLM serves the original NVFP4 checkpoint with the LoRA adapter applied on top. The trainer runs on a BF16 dequantization of the same weights and updates only the adapter (rank 32, alpha 64), which covers attention, the MoE latent projections and all routed experts. It also replays the rollout’s MoE routing (R3), and only the adapter is synced back to vLLM after each step.
We trained with GRPO on DAPO-Math-17K for 150 steps on 16 GB300 GPUs, sampling 8 responses for each of 32 prompts per step with up to 4K tokens per response. The accuracy on AIME-2024 (mean@8) went from 0.56 before training to 0.85 by the end of the run. Throughout the run, the k3 KL between the trainer’s and vLLM’s log-probabilities held near 2×10⁻⁴. More details are available in https://github.com/verl-project/verl/pull/8257. In the vLLM ecosystem, Titan RL also uses vLLM as its rollout engine to provide day-0 RL support.
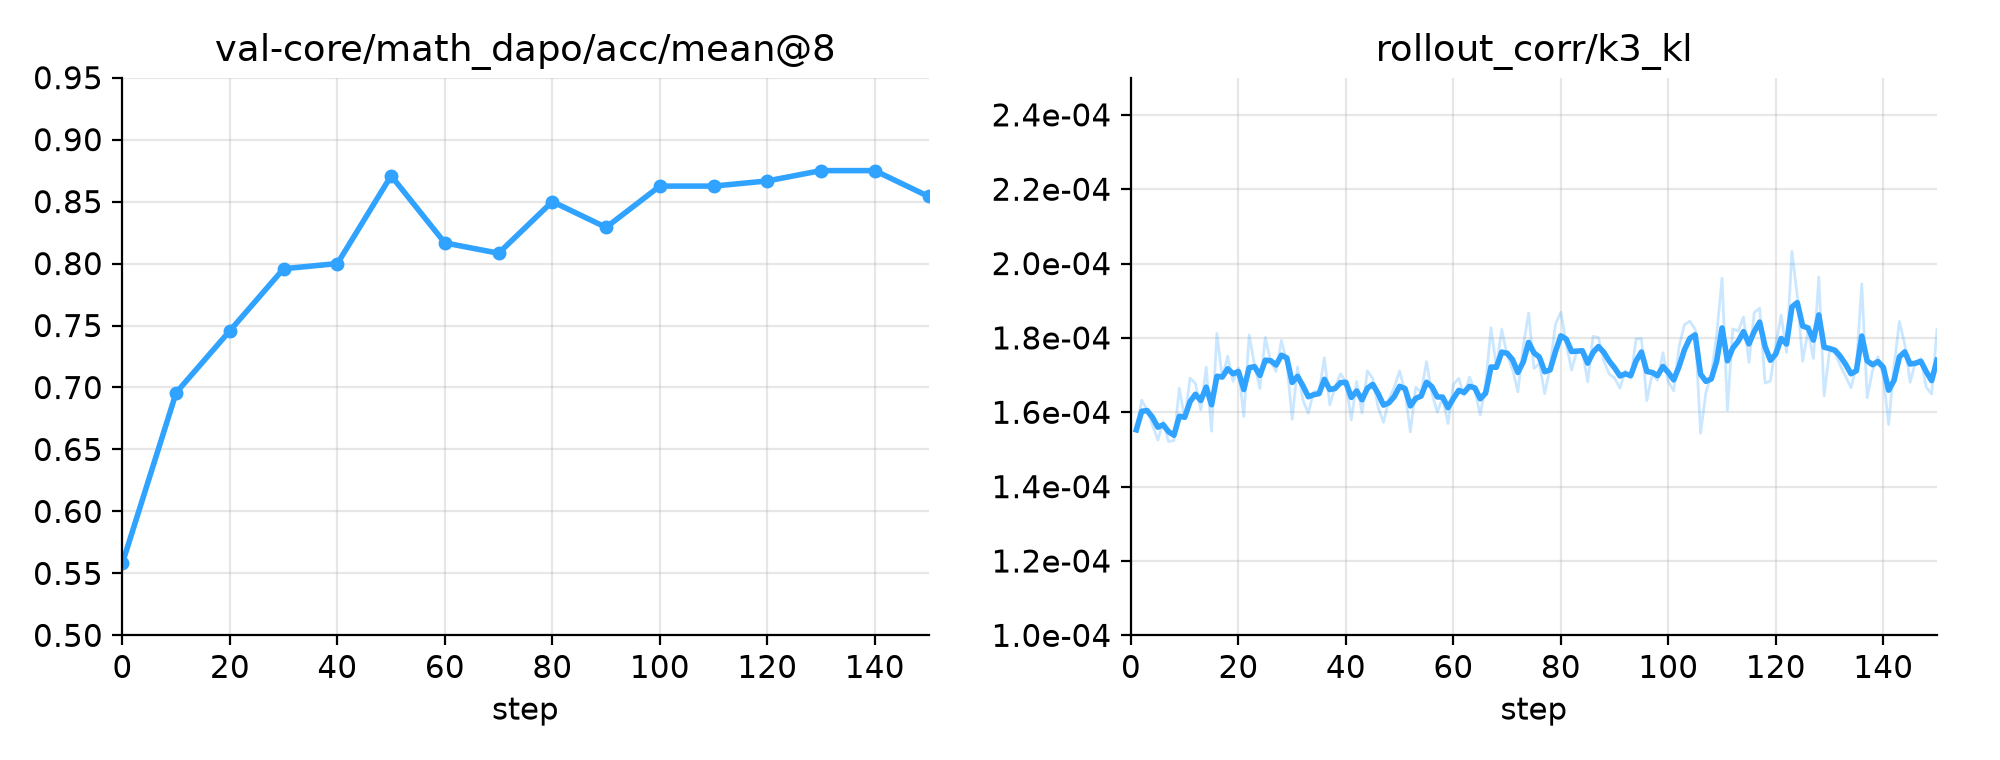
Muse Spark Open LoRA RL results
Acknowledgement
We extend our sincere gratitude to the teams at Meta Superintelligence Labs and the vLLM community for their close collaboration in delivering Day 0 support for Muse Spark Open on vLLM. We also thank Inferact for training the DSpark speculator and TPU integration, alongside NVIDIA and AMD for their vital hardware optimizations.
Contributors:
- Inferact: Jie Li, Zifeng Mo, Zixi Qi, Jeff Ma, Ziqi Zhao, Dakai An, Ao Shen
- Meta: Beto de Paola, Sidhartha Reddy Potu
- Nvidia: Cyrus Chang, Duncan Moss, Marek Pikulski, Seong Hee Lee
- AMD: Andy Luo, Hongxia Yang, Haichen Zhang
Share: