Hyper Optimizing Kimi K3 in vLLM: Moving Fast and Responsibly
October 16, 202612 min read
Benjamin Chislett (NVIDIA)
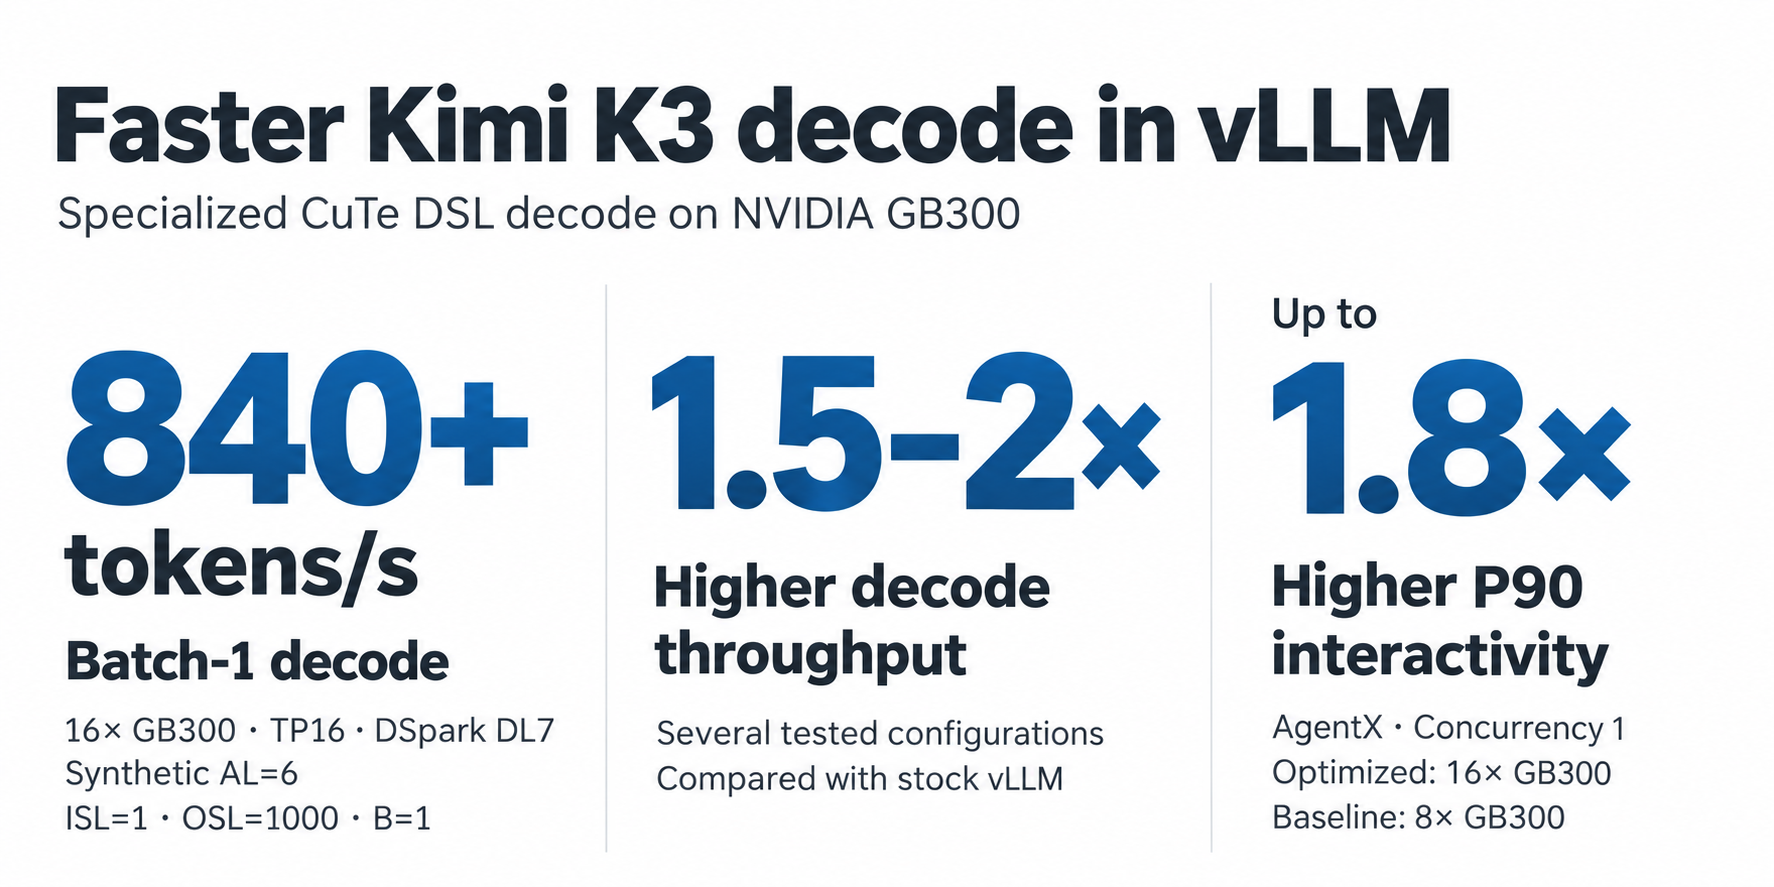
Kimi K3 decode performance on NVIDIA GB300.
Coding agents can now help with some of the hardest parts of model optimization: writing complex GPU kernels, performing cross-operator fusions, overlapping computation with communication, and tuning execution across different batch sizes and GPU configurations. For Kimi K3, we used agent-assisted development to build a unified CuTe DSL decode path on the NVIDIA GB300, covering attention, MoE, and communication across 8 or 16 GPUs. The optimizations deliver over 840 tokens/s at batch 1 on 16 NVIDIA GB300 GPUs with DSpark (synthetic AL=6), 1.5–2× higher decode throughput in several tested configurations, and up to 1.8× higher P90 interactivity on the AgentX workload.
Agent-optimized inference code is outpacing our review and maintenance workflow. The manual review process of understanding every line of every kernel, mapping out potential issues, and testing every supported configuration, is very time-consuming work. On the other hand, if we omit this work then we risk shipping buggy software that could fail in production.
There is a clear line-of-sight on how to achieve both goals: we need to change how we organize performance work. Alongside agentic optimization, we need to design systems that allow automatic verification of reliability and performance, and we need to structure the software to enforce isolation and risk minimization by design.
The proposed fast-track model optimization RFC provides a foundation for this approach. Our guiding principle is to decrease review burden while managing risk. To accomplish this, we:
- Isolate changes. Keep optimizations within the model’s code.
- Bound the scope, preserve the core features. Define the supported hardware and workloads but preserve must-have features for production LLM use.
- Validate correctness systematically. Run an established suite of performance and correctness benchmarks to ensure integrity and reliability, and strictly better performance on all supported configurations.
- Scale validation. Let contributors run standard evaluations on their own GPUs and share reproducible results before requesting maintainer attention.
Kimi K3 is our first contribution following this approach. This post covers how we optimized Kimi K3, how we build the confidence needed to ship and maintain those optimizations, and the performance results.
Table of Contents
- Part 1: Optimizing Kimi K3
- Part 2: Moving Fast and Responsibly
- Part 3: Performance Deep Dive
- What's Next
- Acknowledgements
Part 1: Optimizing Kimi K3
This contribution introduces a new decode path for Kimi K3 which fuses and replaces almost all operations with customized CuTe DSL kernels, tuned for certain subproblems. It targets NVIDIA Blackwell GPUs with 8 or 16 GPUs, decode batches from 1 to 64, and optional decode context parallelism for long contexts. The GPUs share one NVLink domain with multicast support. For more details, please refer to the PR.
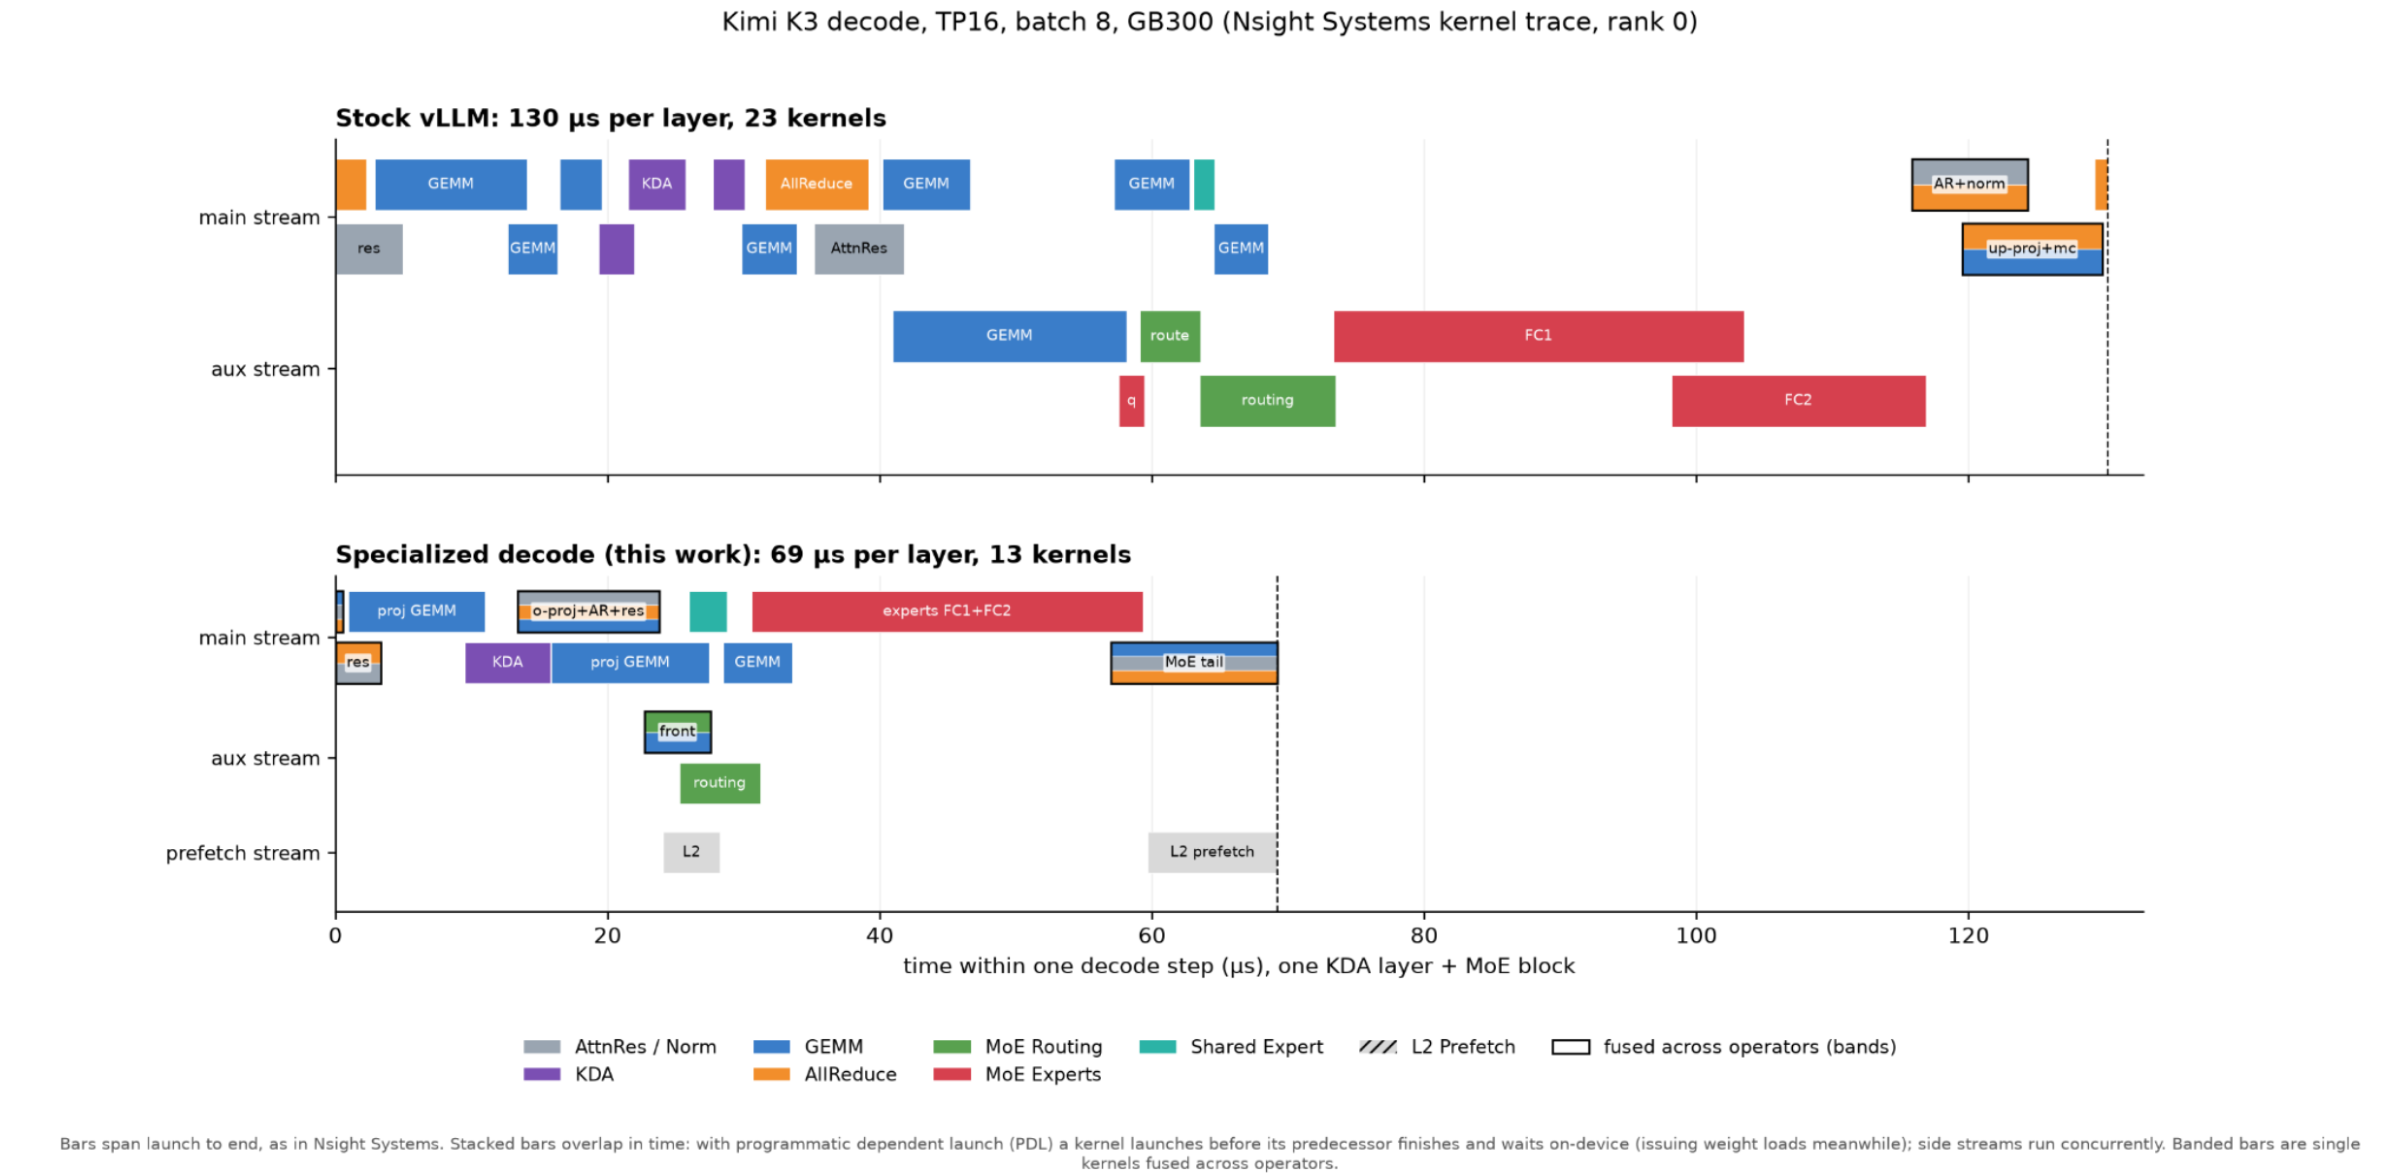
Kimi K3 kernel timeline: stock vLLM uses 130 microseconds and 23 kernels per layer; specialized decode uses 69 microseconds and 13 kernels.
1. Tune shapes for the workload
Different batch sizes need different kernel choices. For attention input projections, we use specialized small-matrix kernels at batch sizes 1–2 and split-K kernels at larger batches, which divide the matrix multiplication across more GPU workers. All such projections have been finely tuned to launch well-sized kernels that fully utilize GPU resources and overlap memory reads / communication and compute work as much as possible.
KDA also uses an optimized CuTe DSL decode kernel, with scheduling tuned for the batch size and number of attention heads on each GPU.
For long contexts, decode context parallelism (DCP) splits the KV cache across GPUs. Each GPU computes attention over its local portion, and a tuned fused kernel combines the partial results with v-proj and gating.
2. Overlap computation and communication
We fuse attention output projection directly to its all-reduce and the following attention-residual computation. GPU kernels publish partial results into NVLink-accessible buffers, and receiving kernels combine them and continue the computation. Some small-batch configurations fuse the producer and consumer into one kernel. Data exchange is done with a fence-less approach with minimal overhead.
At larger batches, the implementation switches to a two-stage reduction: GPUs first combine assigned portions of the output, then distribute the results. This reduces the data movement between GPUs.
3. Improve MoE scheduling and overlap
Although the experts already use tensor parallelism, the baseline computes the full router scores and latent input projection on every GPU. We split these calculations across the TP ranks and combine each rank’s share into one matrix multiplication. The GPUs exchange the results over NVLink. This reduces repeated computation, weight reads, and kernel launches before expert execution begins.
The shared expert runs on a separate stream. Its work overlaps with routing or routed-expert computation, depending on the configuration. The schedule controls how many GPU resources each operation uses, and is carefully tuned to ensure well-balanced parallelism without contention. Details are in experts_runtime.
4. Prefetching upcoming weights into cache
In small-batch inference, we are often memory-bound: limited by the speed with which we can load the weights from memory. Some phases cannot fully utilize the available memory bandwidth, such as communication: while this work happens we can run a dedicated kernel on a side stream to ensure that once the communication completes, the weights for the next operation will have a much higher cache hit rate.
Part 2: Moving Fast and Responsibly
Kimi K3 is just one of the first examples. We believe the community can build this together, to bring more models, GPUs, and workloads towards the speed of light.
Different contributors/agents will find different opportunities: a better communication schedule, or a fusion that helps a particular deployment. But if every contribution arrives with different assumptions, incomplete tests, and a benchmark that is hard to reproduce, the validation and maintenance work quickly becomes the bottleneck, or we risk shipping broken code. We need a common way to turn those ideas into improvements that users can rely on for their long-term production use-cases.
This changes what we ask agents to deliver. We should set clear expectations on testing, validations, and requirements for the code agents produce. Agents will construct tests, run comprehensive evaluations and benchmarks, investigate failures, and document the conditions under which the optimization works. Human reviewers still judge the design and the evidence, but they can start from a high-level abstraction, instead of a line-by-line code review.
Building on the proposed fast-track RFC, we organize this work around four principles.
1. Isolate changes
Keep model-specific optimizations within the model’s code. This makes the affected paths easier to identify and reduces the blast-radius a reviewer needs to consider.
Isolation also needs to hold at runtime. Reviewers should be able to trace when the optimized path is selected, what state it changes, and how execution returns to the standard path.
This constraint does exclude some optimizations: input preparation, sampling, and KV cache management can cause overhead that isolation excludes. This is a consequence of the design and is largely intentional: these components are all shared among most vLLM deployments, and changing them to optimize for a specific workload risks breaking dozens of other stable vLLM configurations. Work on these components is important, and should involve core maintainers much more closely than the fast-track would permit.
2. Bound the scope, but preserve the user’s features
An optimization does not need to improve every deployment to be useful. It can target a particular GPU, parallelism setting, or range of batch sizes. Clear boundaries make the work easier to tune and give us a defined set of configurations to validate.
For K3, the initial hardware validation covers GB300 with TP8 and TP16, decode batches up to 64, speculative decoding with various draft lengths, and decode context-parallel configurations within one NVLink domain.
These boundaries describe where the optimization applies, but not cutting ‘feature coverage’. Production deployment needs fundamental features that make the endpoint useful. Features like full-context serving, temperature sampling, and structured output cannot be “optimized away” or “opt-out”, they are first-class serving features and belong to the validation plan alongside kernel shapes and numerical checks.
3. Validate correctness
Kernel tests and model evaluations answer different questions. Kernel tests check numerical results across shapes and input values. Model evaluations check whether the complete execution path preserves the model’s answers. We need both.
The tests must actually exercise the changed code. A small-batch optimization needs evaluation at small batches. An attention kernel change needs long-context coverage. Tests that silently use the standard path provide little evidence about the optimization and are a common trap.
K3 development shows why this matters. Our audit discovered that the compiler moved activation reads ahead of a synchronization wait. The fix restricted that load type to static weights. Such errors can survive simple functional checks and require targeted investigation.
Additionally, long-context and long-generation evaluations such as MRCR and AIME25 surfaced sensitive numerical issues in attention and communication kernels that were not reproducible in standalone kernel tests using mock inputs and/or consistent launch timings.
4. Check performance broadly
A headline speedup is a starting point. We also need to know how the change behaves across the workloads it affects. That means sweeping batch sizes, context lengths, and supported parallelism configurations. MoE measurements should include real prompts because expert selection affects which weights are read and how much work can be reused. Pure decode results should also be distinguished from workloads that mix prefill and decode.
Reliable validation also takes GPU time. The related Bring-Your-Own-GPU evaluation RFC proposes standard evaluation images that contributors can run on their own hardware. Reproducible result bundles and submissions linked to GitHub PRs would make the evidence much more accessible. Different evaluation tiers and shared community compute would help expand coverage while managing GPU demand and reducing pressure on project-funded CI.
Part 3: Performance Deep Dive
Decode performance with DSpark
With DSpark, Kimi K3 reaches 842 tokens per second on 16 NVIDIA GB300 GPUs in the controlled AL=6 benchmark. That is 1.73× faster than stock vLLM with the same speculative decoding setup. Refer to the PR for a full results table.
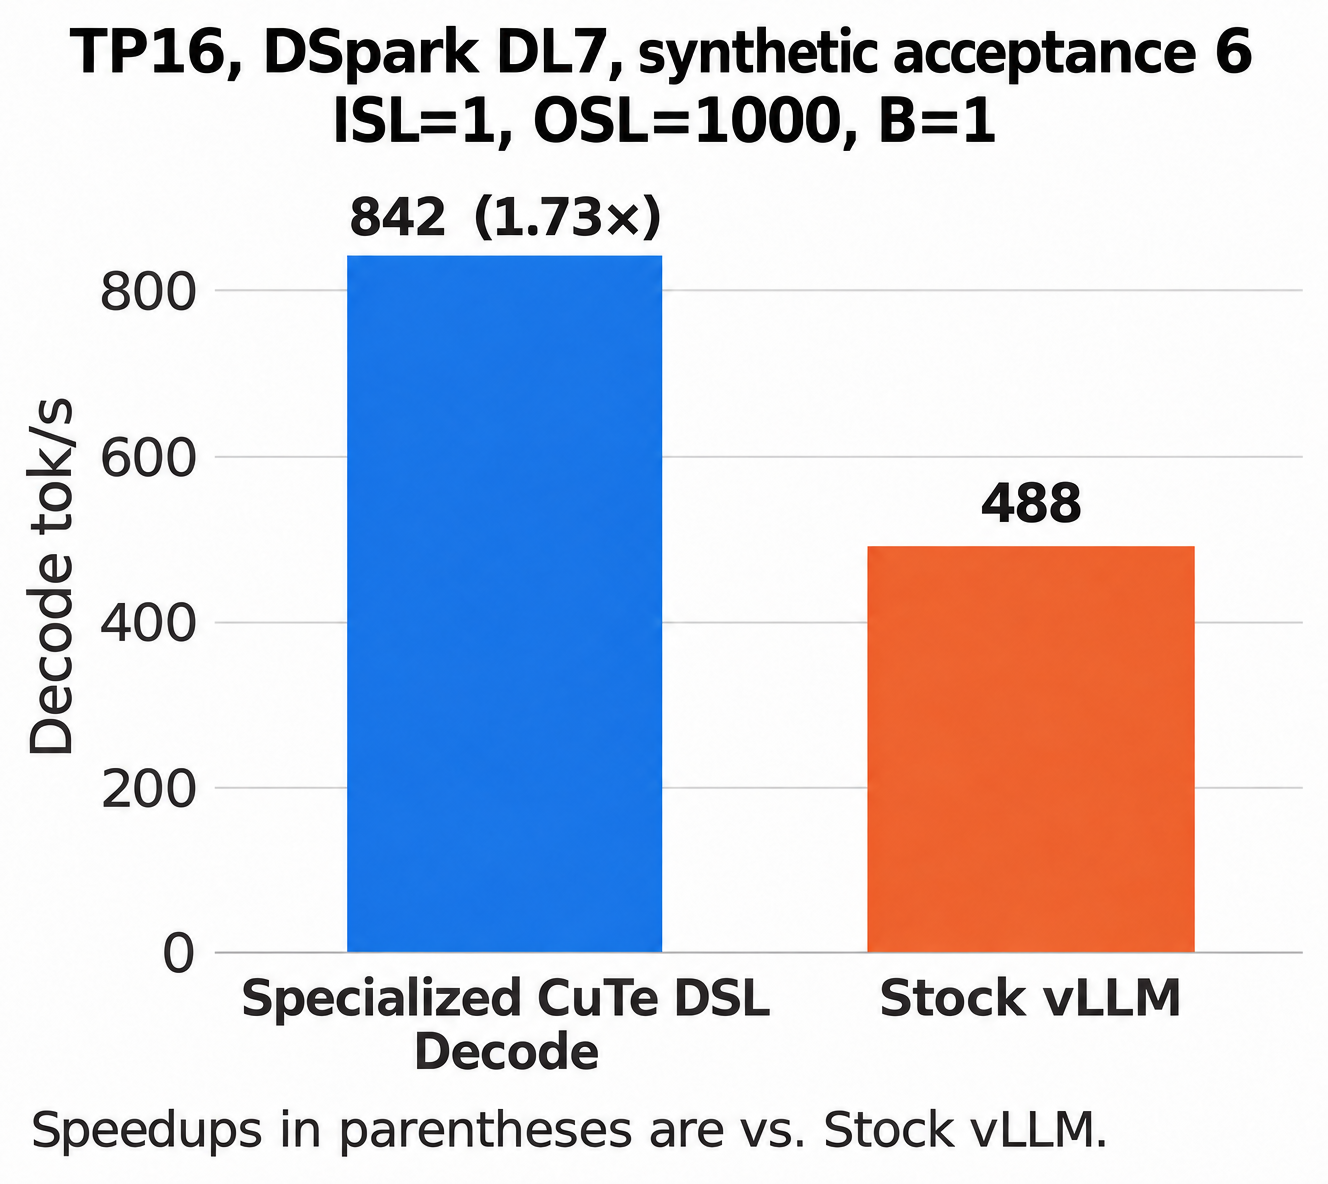
Kimi K3 at batch 1 with TP16, DSpark DL7, and synthetic AL=6: 842 decode tokens/s versus 488 for stock vLLM, a 1.73x speedup.
Setup: TP16, DSpark with seven draft tokens, synthetic acceptance length of 6, DL=7, ISL=1, OSL=1k, batch size 1. TPS measures aggregate decode throughput and excludes prefill.
Decode performance without speculation
The improvements span across the tested batch range. TP16 retains a 1.62–1.71× gain at batches 16–64, while TP8 delivers 1.31–1.43× over the same range.
| Batch size | TP8 tokens/s | TP8 speedup | TP16 tokens/s | TP16 speedup |
|---|---|---|---|---|
| 1 | 193.3 | 1.58× | 256.4 | 1.88× |
| 2 | 317.8 | 1.50× | 436.7 | 1.92× |
| 4 | 540.6 | 1.55× | 702.5 | 1.81× |
| 8 | 820.1 | 1.45× | 1,157.9 | 1.79× |
| 16 | 1,274.8 | 1.43× | 1,758.3 | 1.71× |
| 32 | 1,702.6 | 1.33× | 2,550.9 | 1.64× |
| 64 | 2,375.9 | 1.31× | 3,606.1 | 1.62× |
No speculative decoding. Throughput is for the entire TP group.
Improvement on AgentX
Our optimized Kimi K3 implementation also delivers 1.8× higher P90 interactivity at concurrency 1 on AgentX: 403.2 versus 223.7 tokens/s/user. This compares the optimized run on 16 GB300 GPUs with the earlier vLLM result on 8 GB300 GPUs.
AgentX replays traffic patterns from real coding-agent sessions, including long contexts, multiple conversation turns, tool pauses, parallel subagents, and KV-cache reuse. It preserves these workload patterns while replacing private content with synthetic text, testing the serving system under realistic agent traffic. AgentX methodology.
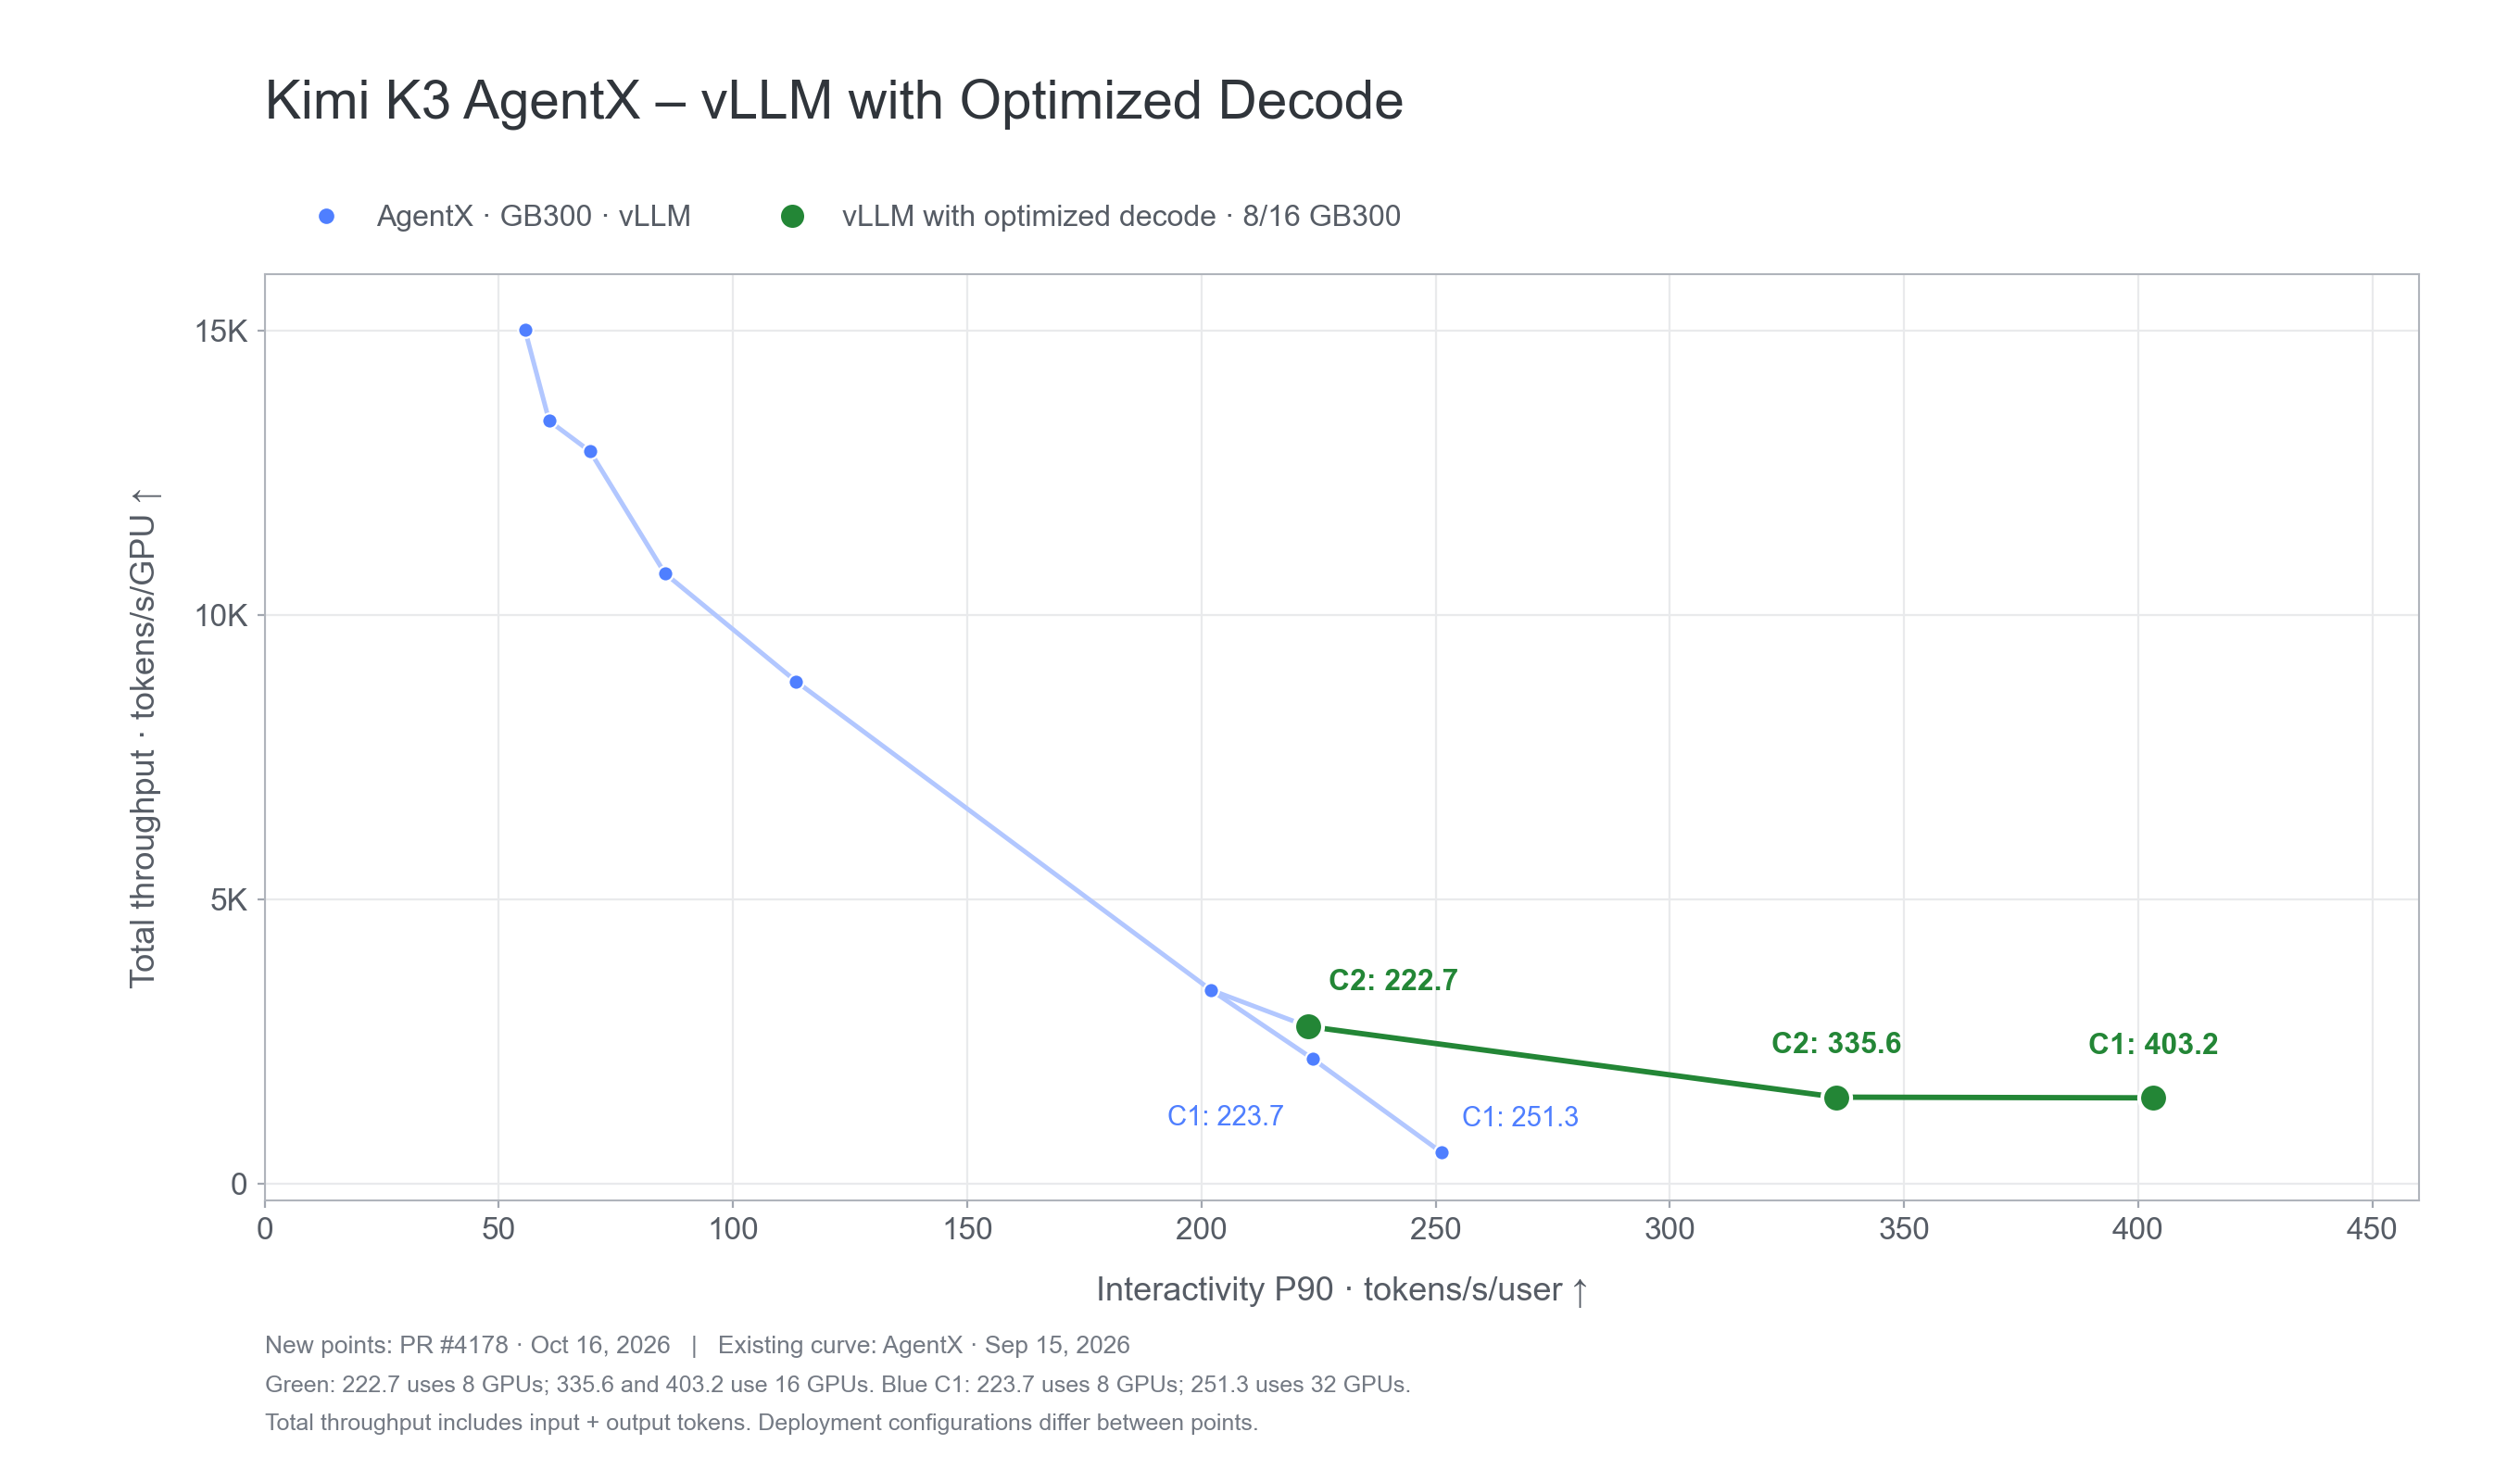
Kimi K3 AgentX results: P90 interactivity versus total throughput per GPU, comparing the earlier GB300 vLLM curve with specialized decode.
What's Next
For DeepSeek-V4.1-Flash, #61868 follows the K3 design patterns: behind the same opt-in decode_backend: latency_specialized switch, the implementation also supports up to 64 concurrent requests, seamless fallback for prefills and mixed batches, and speculative decoding. Instead of chasing a single hotspot, that executor cuts kernels and host work: it fuses all-reduce + mHC at every sublayer boundary, replaces the large-batch MoE and GEMMs with CuTe DSL kernels built for low-latency, deduplicates and shards the indexer’s work, and takes per-step work that stock vLLM runs eagerly on the CPU and replays it as a CUDA graph instead.
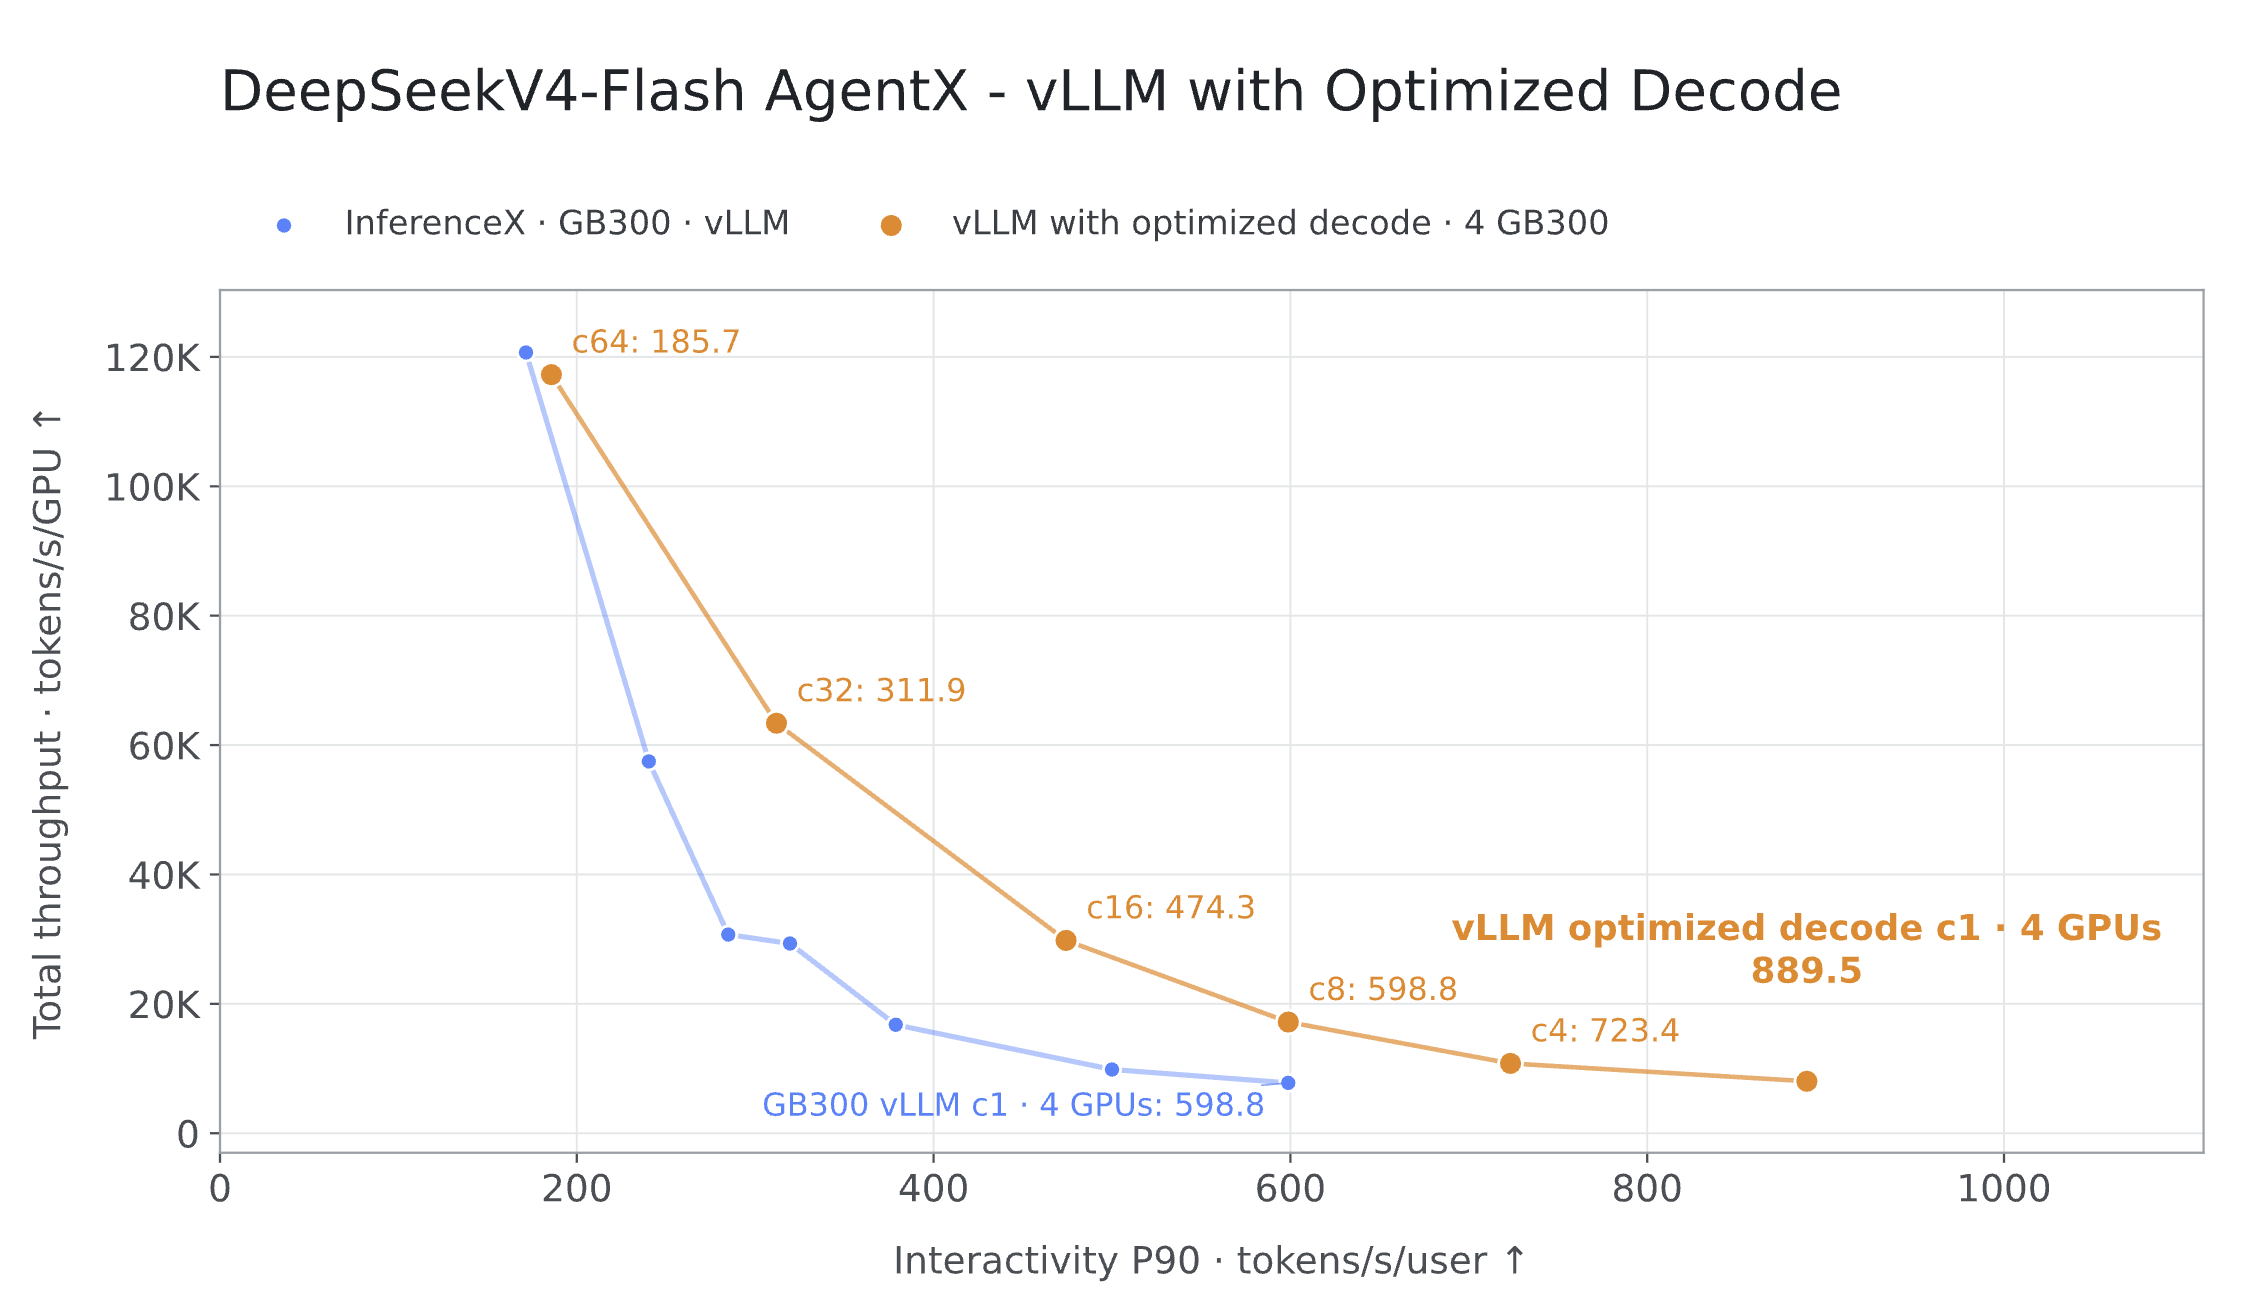
DeepSeek AgentX results on four GB300 GPUs: P90 interactivity versus total throughput per GPU with and without optimized decode.
Within two days of Meta’s Muse Spark Open release, our early results already exceeded 950 tokens per second per user, with seven draft tokens (K=7) and an acceptance length of six (AL=6). More optimizations are underway.
We are also releasing a similar mechanism to optimize the decode latency for GLM5.3 under a low-concurrency scenario too. We’ll share its optimization details and performance results in a follow-up.
For each contribution, we will continue to focus on concrete performance gains, production feature support, and reproducible correctness and performance checks.
Acknowledgements
We would like to thank Rohan Varma (NVIDIA) and Alex Steiner (NVIDIA) for their contributions to this work.
We would also like to thank Woosuk Kwon (Inferact), and Michael Goin and Lucas Wilkinson (Red Hat), for the model refactor and valuable feedback and support.
Share: