The efficient frontier of LLM inference
In the AI industry, we borrowed the term “efficient frontier” from economists. We use it to talk about managing tradeoffs, most often the tradeoff between cost and capabilities for models. A model is a “frontier model” if it offers the highest degree of intelligence at a given cost or size.
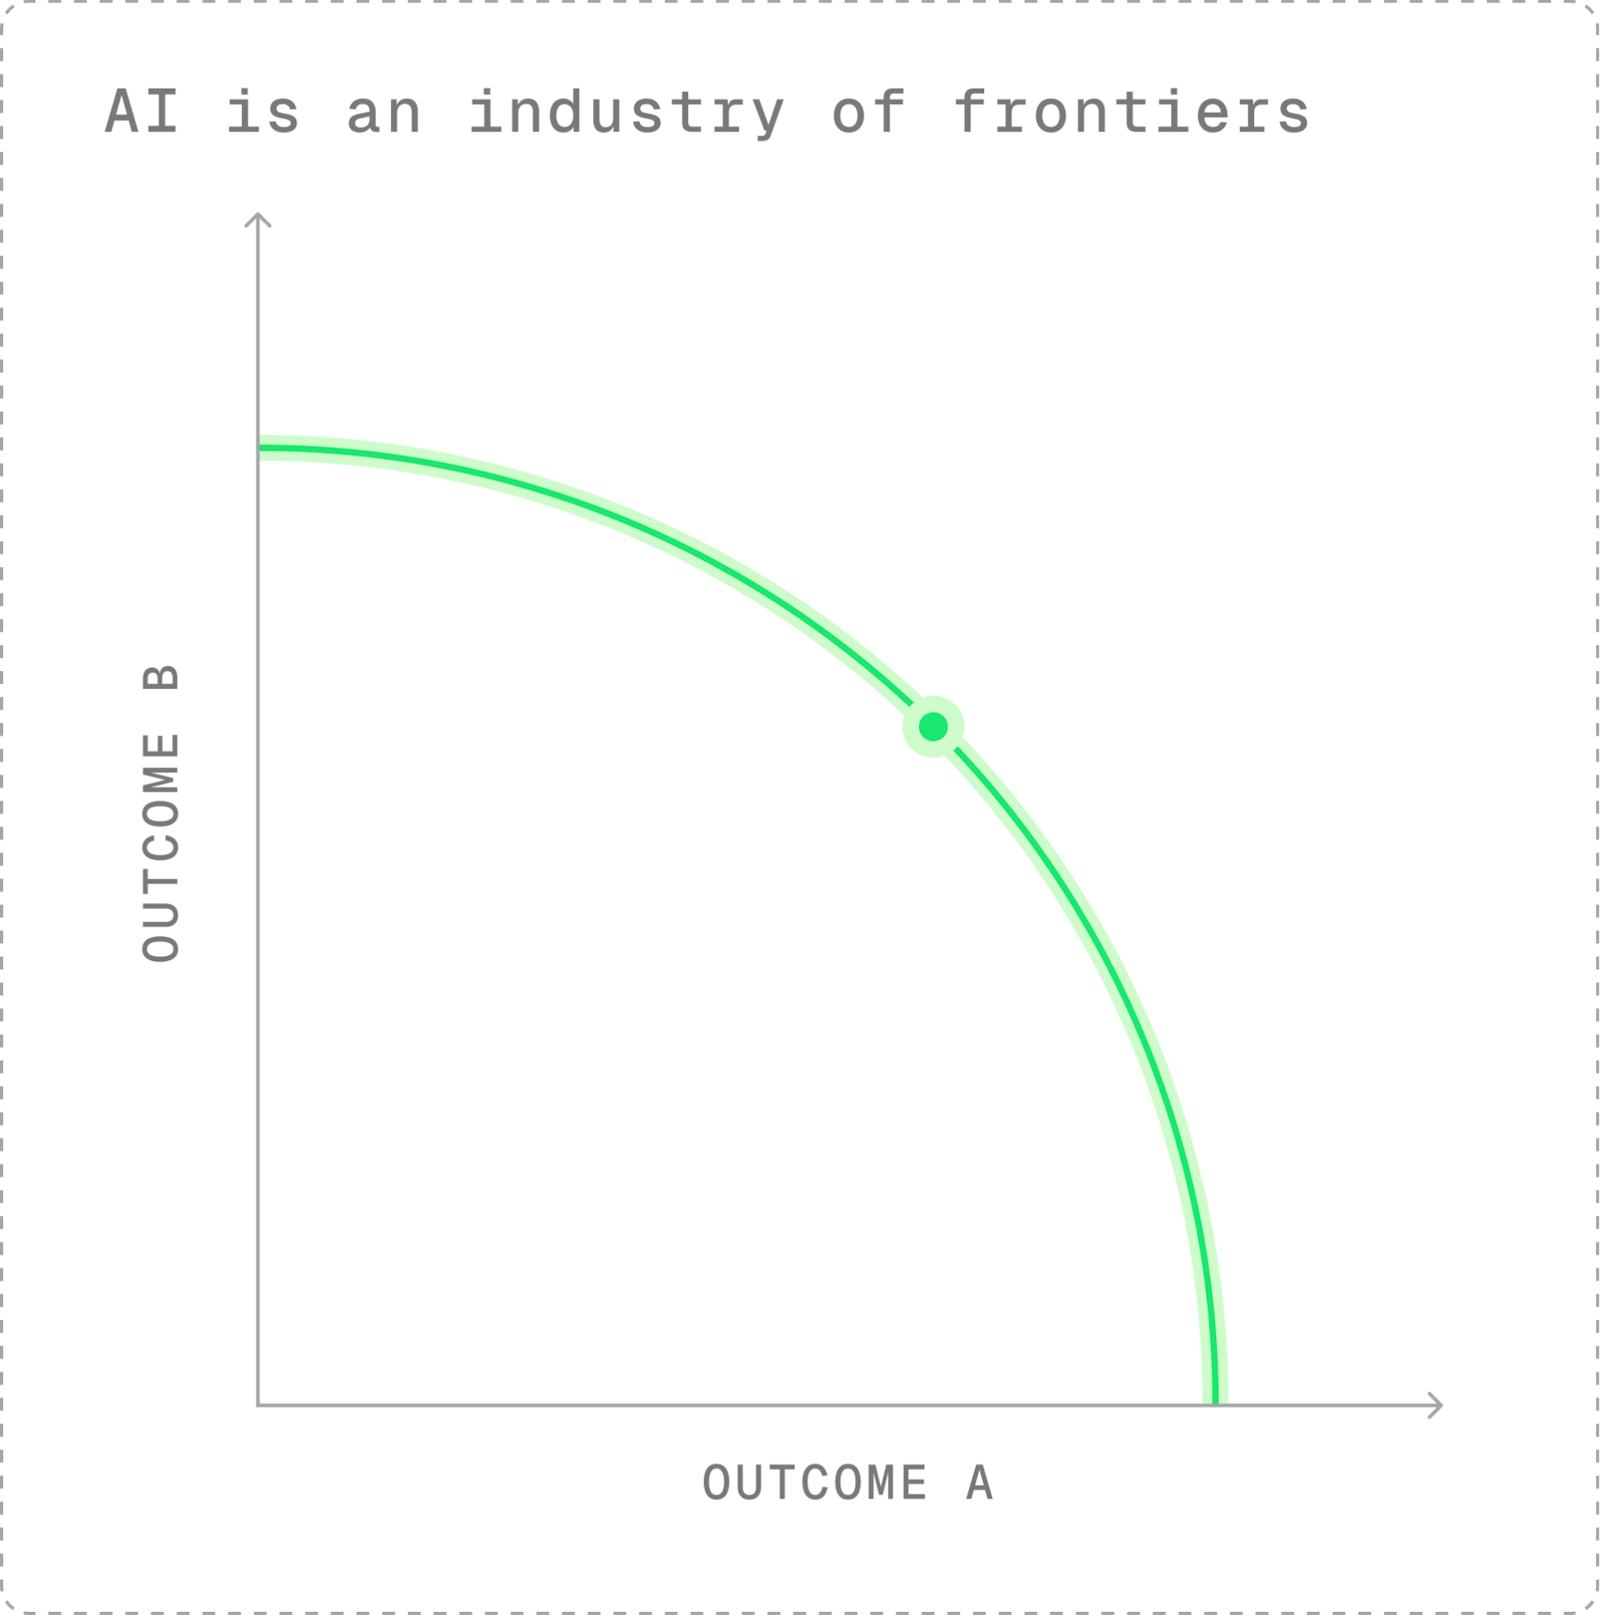
An efficient frontier shows the range of optimal combinations when trading off between two valuable outcomes in a resource-constrained environment.
We also have efficient frontiers in inference engineering. Most often, this is expressed as a tradeoff between latency and throughput (which determines cost), though we can also exchange quality for throughput (via quantization, distillation, and pruning) or intelligence for speed (in the form of reasoning level).
There are two types of techniques available to inference engineers:
- Techniques which make a tradeoff between two factors to move a deployment along an efficient frontier.
- Techniques which push out the entire frontier for a given deployment, creating more overall efficiency which can be allocated to whatever outcome is most beneficial.
Both types of techniques are valuable.
It’s useful to be able to target any point along an efficient frontier by making tradeoffs. Giving up per-user speed makes it possible to build high-throughput, low-cost pipelines for batch workloads. Sacrificing throughput to improve speed makes sense when latency-sensitive users have a high willingness to pay.
And of course, it’s incredibly useful to push out the entire frontier. Unlocking more efficiency creates gains that can be allocated to lower latency, higher throughput, or a combination of the two.
This article details which inference engineering techniques let you target a point on the frontier, and which techniques push the entire frontier out. For this article, we’ll assume we’re running an LLM like GLM-5.3 or Kimi K3 for agentic coding with KV cache reuse enabled and optimal KV-aware routing.
Techniques that manage tradeoffs
Hitting a certain target in production is often less about discovering some novel approach and more about finding the right set of configurations given the nature of the traffic.
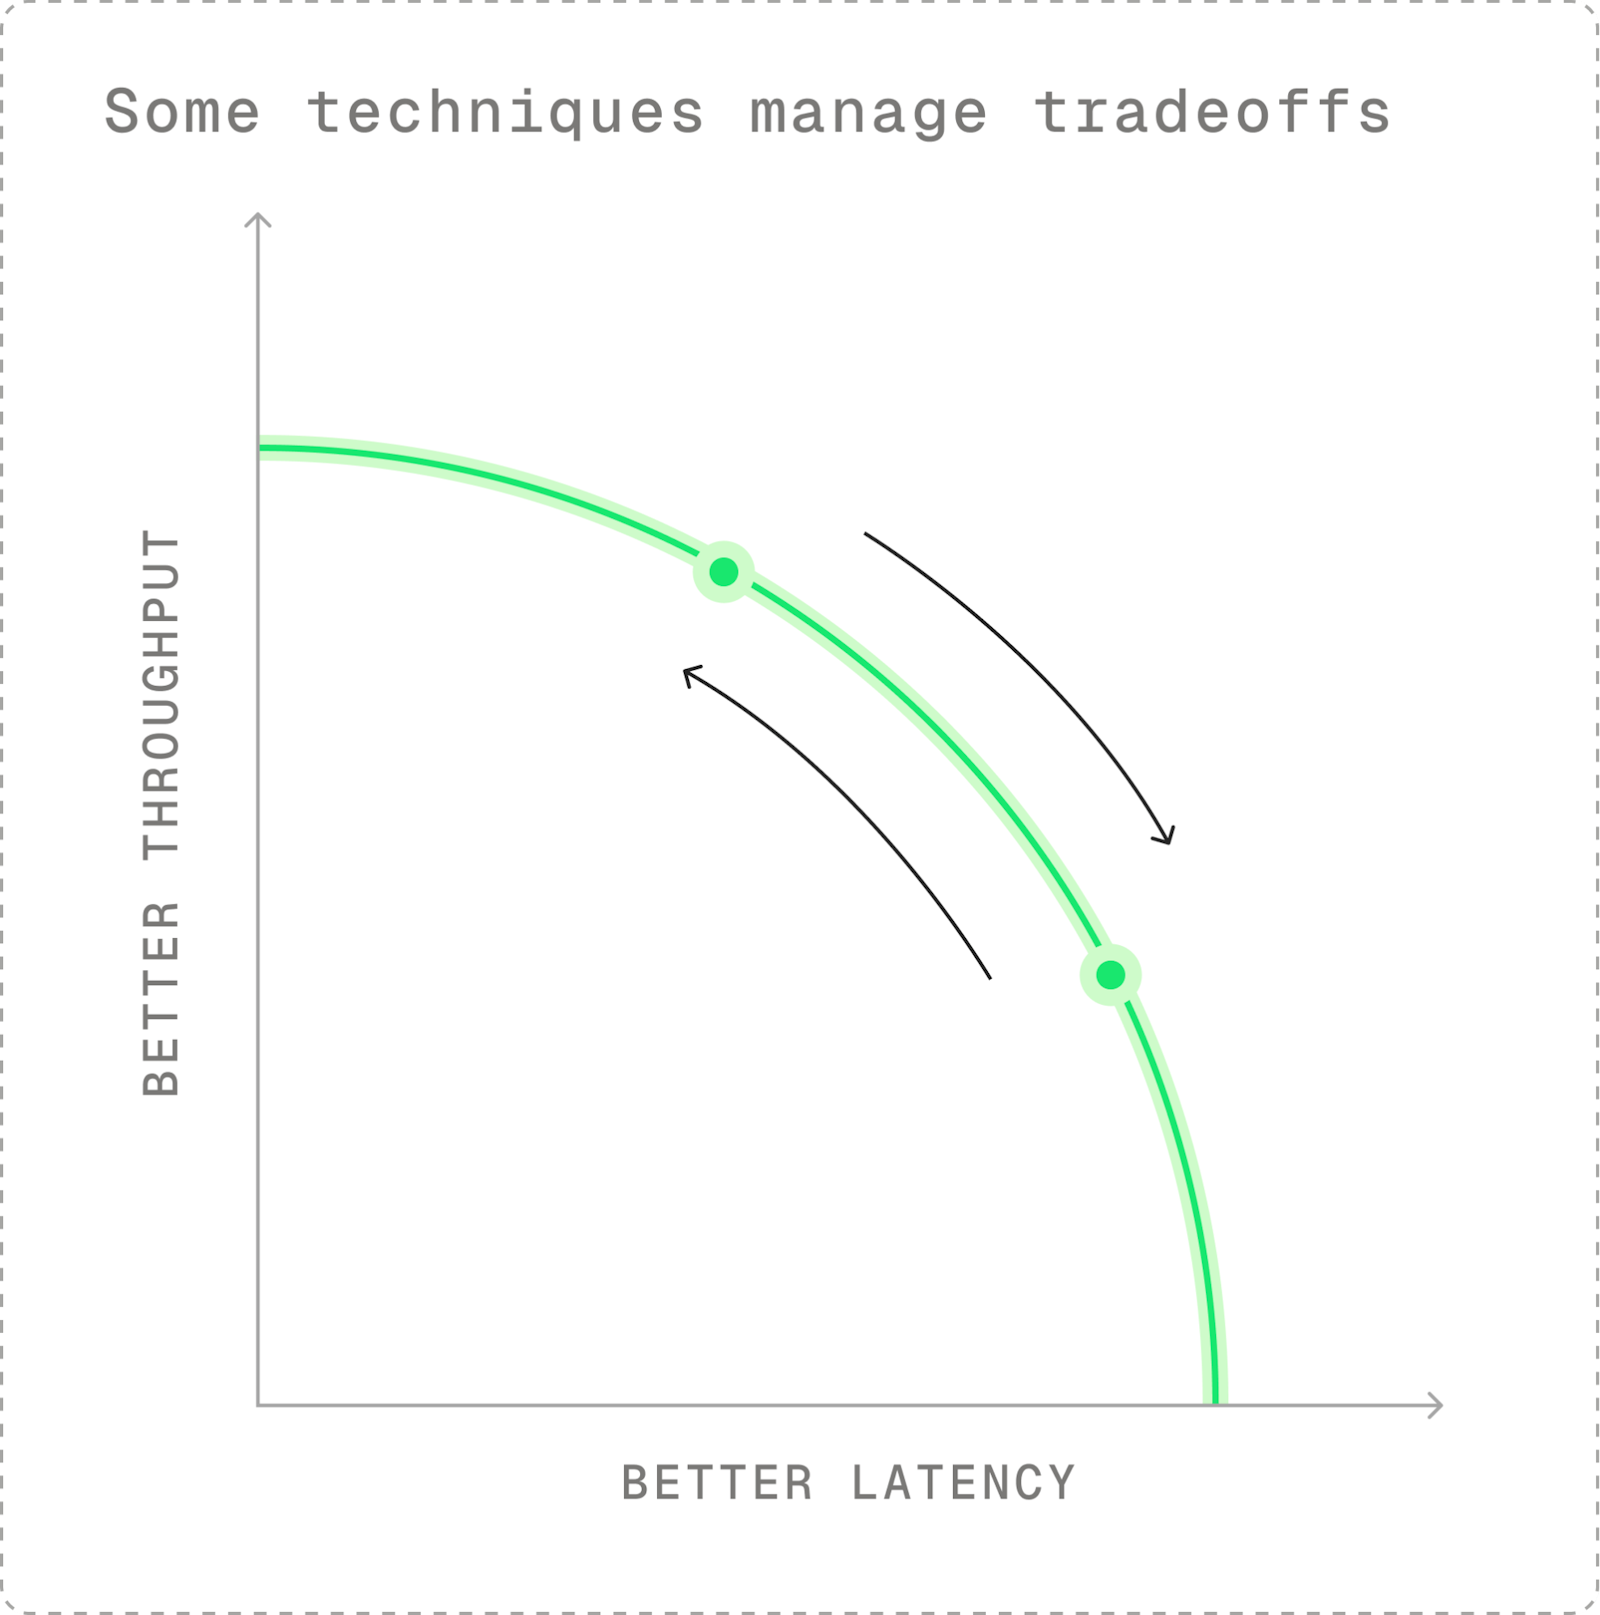
Techniques for managing tradeoffs let you target an outcome along an efficient frontier.
In practice, the efficient frontier is very jagged. Rather than a smooth, continuous line between outcomes, small changes can have big impacts. These cutoff points are often unintuitive and must be discovered empirically through sweeps.
Batch sizing
The most obvious tradeoff between latency and throughput comes from batch sizing. A batch is the number of requests that are processed concurrently. While token-level continuous batching means that there isn’t any latency from waiting for batches to start, the configured batch size determines the per-user latency and the overall throughput.
With small batch sizes, per-user latency is excellent, but few total tokens are generated per GPU. This means the cost per token is quite high. Increasing batch size has the opposite effect: worse per-user latencies, better overall throughput for lower cost.
Parallelism strategy
Today’s LLMs measure in the hundreds of billions or trillions of parameters and must be spread across multiple GPUs. The way in which they are shared, or parallelized, across GPUs can boost either latency or throughput.
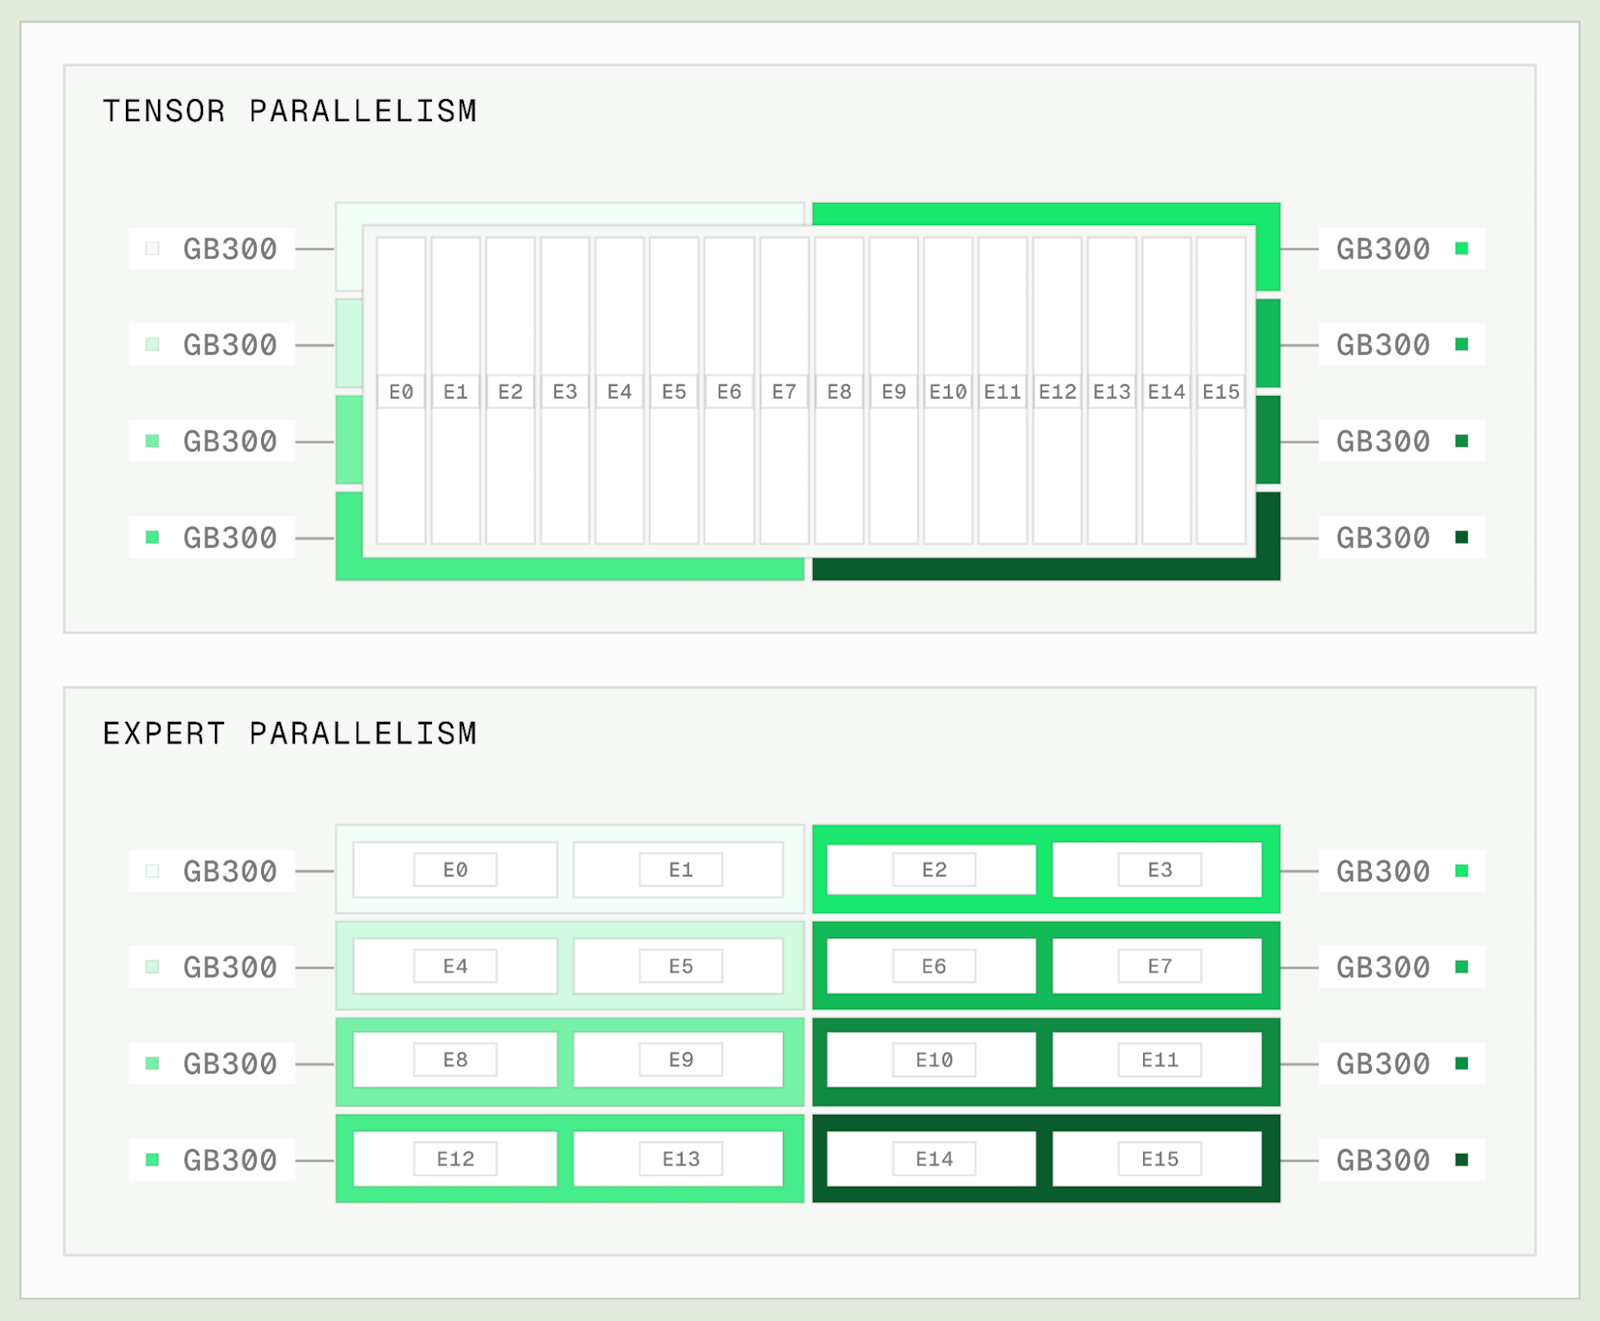
Parallelism splits large models across multiple GPUs.
For latency-sensitive deployments, focus on increasing Tensor Parallelism (TP). While TP has expensive all-to-all communication, it is effective for lowering latencies as these operations are fast over high-bandwidth NVLink interconnects.
Expert Parallelism (EP) can help with both latency and throughput. A lower degree of EP is often associated with better latencies, while wide EP, including EP across a full rack of GPUs, generally supports higher throughput.
Another parallelism technique for improving throughput is Attention Data Parallelism (ADP). This technique replicates attention layers for parallel computation, which boosts system throughput at the expense of per-request speed.
Quantization
Quantization, or running a model with a lower level of precision in weights, activations, and/or KV cache values, improves both latency and throughput. A quantized model pushes out the efficient frontier on serving tradeoffs.
However, quantization introduces a new set of tradeoffs between quality and serving efficiency. This is a particularly jagged frontier, where a large degree of improvement to serving efficiency is possible with little-to-no reduction in model quality, especially when using microscaling floating-point number formats like MXFP4 and NVFP4.
Techniques that move the frontier
These techniques are the ones that make the headlines. Improving overall performance is the most fun part of inference engineering.
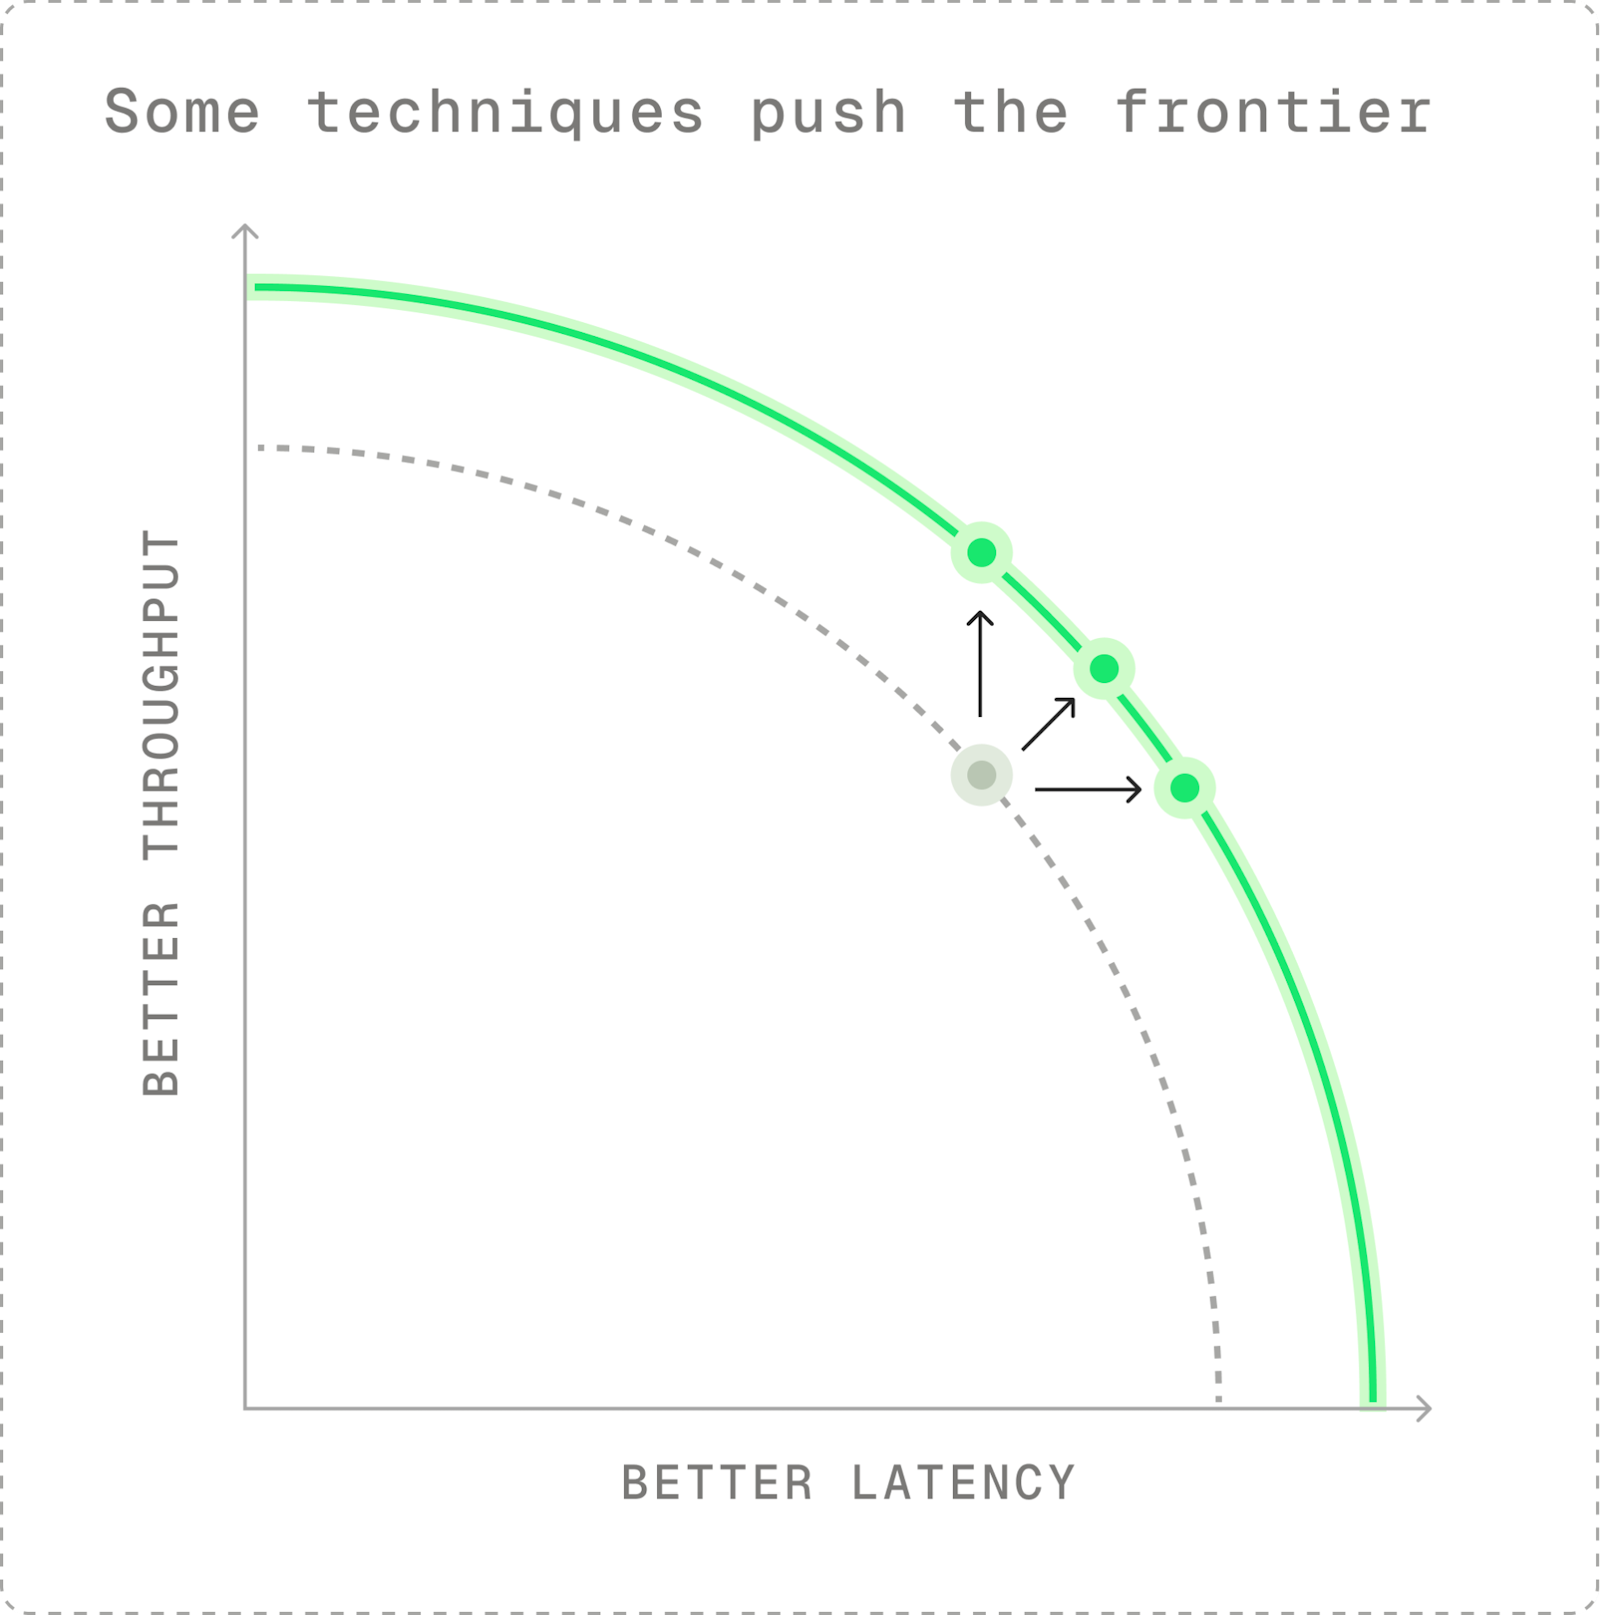
Techniques for pushing out the frontier create universal gains.
The best part is that these techniques often compound. For example, doubling performance from better hardware while also doubling performance from better software means a four times improvement in overall serving, which can be allocated across latency and throughput.
Kernel optimization and runtime improvements
A CUDA kernel is a low-level function that executes a single piece of the inference process, like a matrix multiplication. Improving the performance of individual kernels, as well as the end-to-end performance of a forward pass in the inference engine, means fewer resources are needed to generate each token. These efficiency gains compound throughout the stack and push the frontier of performance.
For more on kernel-level performance, read this excellent writeup by Baseten intern Brian Li.
Speculative decoding
Speculative decoding is the process of guessing which tokens a model might generate, then validating those guesses. When speculative decoding was new, this posed a tradeoff between latency and throughput: speculation was expensive, sequence lengths were short, and acceptance rates were low, meaning speculative decoding was only feasible at small batch sizes.
Today, techniques like EAGLE-3, DSpark, and DFlash still compete with the main model loop for resources, somewhat limiting maximum batch sizes. However, thanks to the strong performance of these techniques, especially on code generation where output token sequences are relatively predictable, they yield efficiency gains from skipped forward passes in addition to the raw reduction in latency in the form of more tokens per second per user.
Disaggregation
P/D disaggregation, or separating prefill and decode onto dedicated workers, is a strategy for optimizing high-volume deployments of LLMs. Running prefill and decode independently means that workers can be optimized for the unique characteristics of each phase of inference, and that the ratio between prefill and decode workers can be adjusted to match the input and output sequence lengths and cache hit rates from incoming traffic.
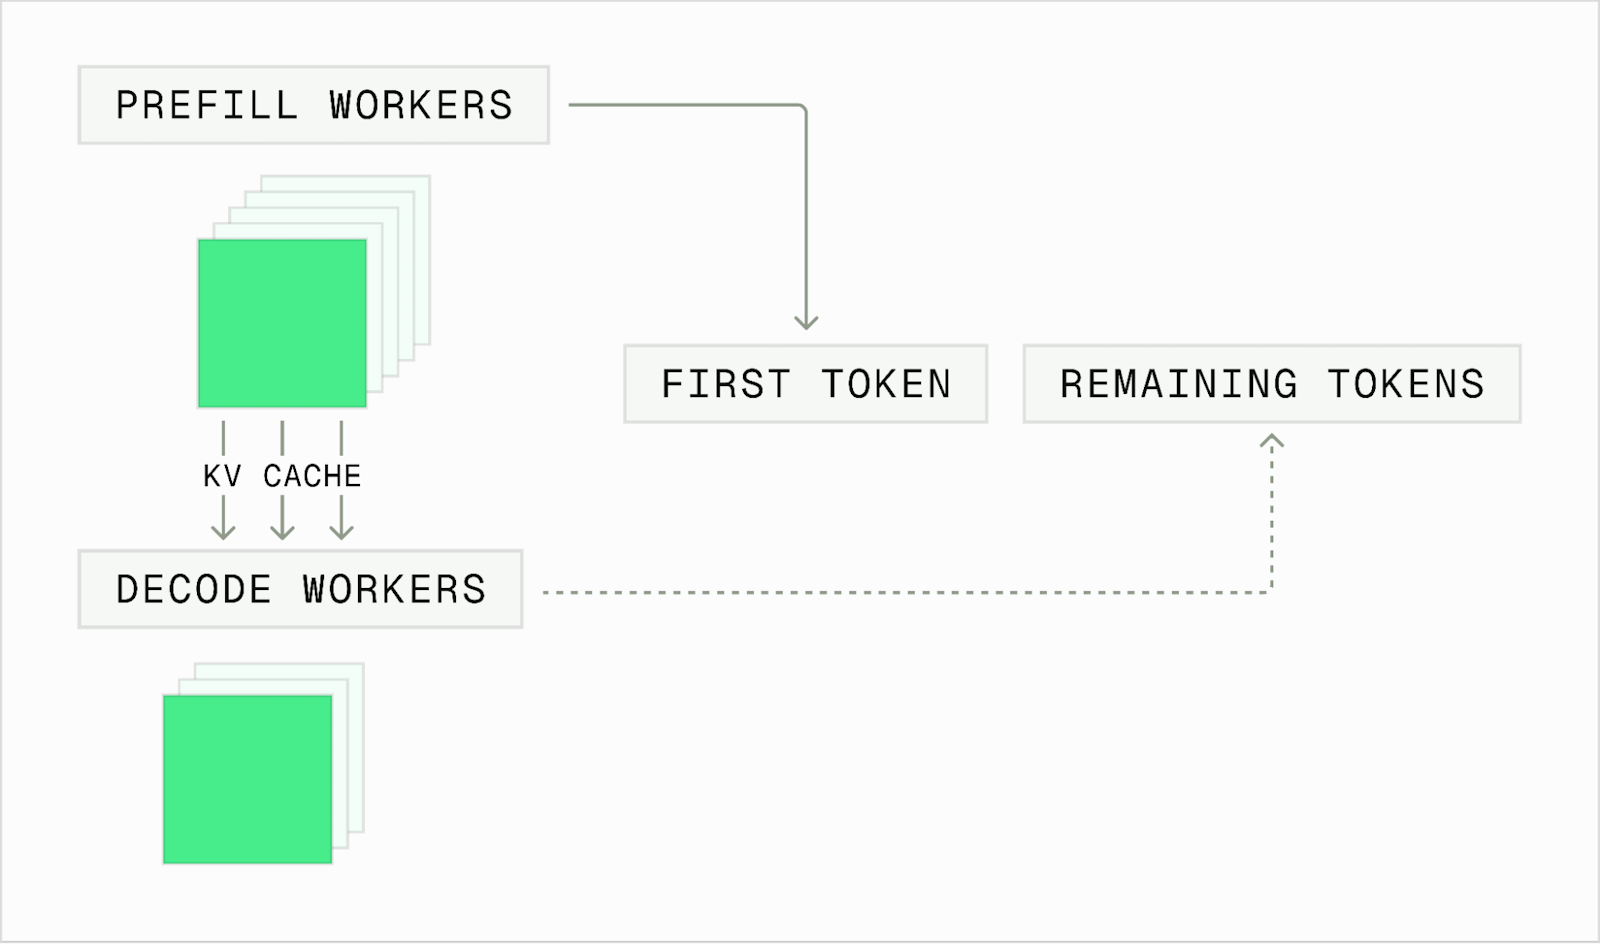
In practice, disaggregation is often most useful for increasing throughput while keeping latencies the same or slightly better.
This article provided a basic overview of techniques for managing tradeoffs versus techniques for improving systemwide performance. For more detail on every technique mentioned in this article, read my free book Inference Engineering.