The rise and fall of Jev
This is a quick note on how the industry’s reaction to Jev reveals the desperate state of AI. I’ll dissect:
- What is Jev, how was it hyped and why it spread like mass hysteria? Jev isn’t dead but its hype cycle is.
- What are the noteworthy innovations since ChatGPT brought “AI” to the mainstream?
- How is the industry starved from real innovation?
- What we’re still missing after 4 years of
revolutionincremental improvements?
The point is to use Jev’s hype cycle to show the manipulative marketing techniques that are too familiar with at this point.
Jev
You probably don’t need an intro to Jev at this time because since its introduction 33 days ago, it has been all the rage!
But if you were clever enough to ignore it, here’s what actually matters:
Jev is basically a general purpose classifier (e.g. quick judgement). What makes it interesting is that you don’t have to train it with a lot of data (although that lack of special-purpose training negatively impacts its utility).
Calling it a “decision model” is a bit far fetched especially since it cannot even see (rival open-weight models have multi-modal features) or reason (that’s how it’s so cheap).
The idea behind Jev isn’t new! The idea of non-autoregressive decision models with RL goes back more than a year ago. The original author is pissed but as we’ll see drama is an inseparable part of AI hype.
Hype
I want to walk you through the emotional roller-coaster I went through when I read their announcement via hackernews:
At OpenAI, I helped build the methods that made language models useful at following instructions and talking with people. That work ended up as the research behind ChatGPT.
😎 So the founder was behind ChatGPT, one of the fastest-growing products in history. I’m listening…
At the time, I thought maybe chat models would lead to AGI, but despite the hype it became obvious to me that there was something really big missing.
😃 Oh, my god! This is it! ChatGPT is missing something big and he’s about to reveal it! We’re one step closer to AGI if we haven’t reached it already! I’m thrilled to read more…
After two years in stealth, countless technical challenges, and research breakthroughs… I am beyond excited to announce
😱 Spit it out! I’m beyond excited to read this…
TypeSafe AI is releasing our first System One Model
😯 Wait what?!! “System one”?
Do you understand what you’re talking about? Here’s my recollection of how Daniel Kahneman defined the two systems:
- System one: fast, cheap (in terms of computational power), emotional, unconscious and judgmental.
- System two: slow, expensive (takes more brain power), logical, conscious, and more elaborate.
If Jev is system one then LM is system two? It can’t even handle logical reasoning!
Most importantly Jev came with another interesting framing:
can’t hallucinate
Hallucination is one of the biggest problems with the current generation of language models but no hallucination doesn’t mean the response is logically correct. In Jev’s context, it just means that the output matches the schema.
Technically conventional language models can gain this ability by bolting a control loop (e.g., type checker, JSON schema parser) on top. Jev does this much faster and without reasoning. It’s in the name:
We named Jev after William Stanley Jevons. We expect machine intelligence to follow a similar path to coal, after steam-engine efficiency led to an increase in demand.
I don’t know Jev’s architecture because in the true ex-"Open”AI employee tradition, not much is released (probably in the name of “safety” or “moat”). But that doesn’t stop them from dropping jargons:
We built a new […] training method we call Reinforcement Learning for Calibrated Decisions (RLCD).
Note: RLCD rhymes with the “traditional” methods:
- RLHF: Reinforcement Learning with Human Feedback
- RLVR: Reinforcement Learning with Verifiable Rewards
They even claim:
Jev is neither small nor an LLM, hence being off the intelligence Pareto curve.
Fortunately, there’s no shortage of similar models, some of them with even better performance (Laya, Kev, Nimble, NanoJev, etc.)
So let me sum up the marketing strategy:
- Name dropping: former ChatGPT creator, Jevons’ paradox, Pareto curve, System one
- Big claim: cannot hallucinate, exponentially faster and cheaper, entirely new stack, amazing benchmarks and demos
- Ambiguity and jargon: no useful implementation details on the “new training algorithm” or RLCD dataset
- Drama: Laya showed this idea in 1.5 years prior to Jev’s launch
OK, I think at this point we’ve seen this pattern enough to recognize it. I actually think Jev’s team kicked it up a notch to a comical level. Whether their marketing is written by LLM or not, they nailed it.
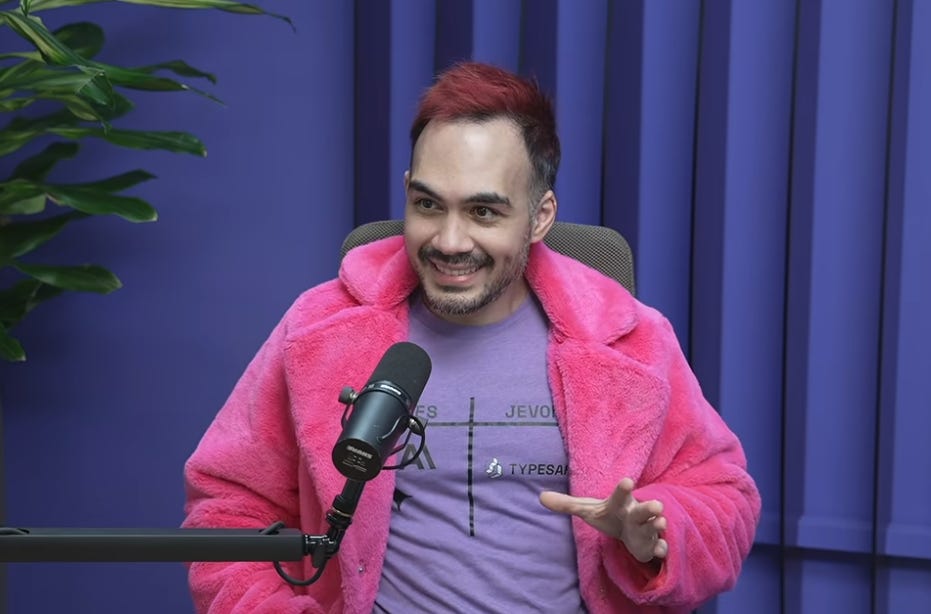
Source: Latent Space Podcast on Youtube
Fortunately, Jev’s initial noise died off almost at the same speed that it blew up. I can only speculate that as more people experimented with it, we realized:
- It cannot hallucinate, but it can still be wrong. It is even more wrong than conventional language models, and in that sense “system one” is the right naming. Although I consider all current generations of language models system one (even the reasoning models) because they do not really reason in the sense that’s expected of system two.
- It is cheaper, but there are open-weight models that beat it in performance/cost ratio (depending on the task). What makes Jev different than frontier-level LLMs is the fact that you can actually run it at the edge (e.g. locally) with matching quality.
Jev is not completely hype, we just went from “Peak of Inflated Expectations” to the “Trough of Disillusionment” in record time:
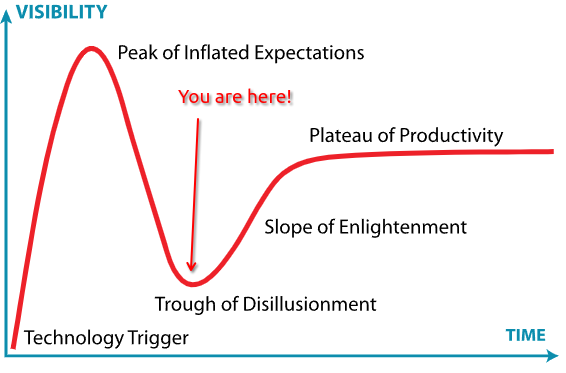
Wikipedia: Gartner Hype Cycle
It’s not dead. Some companies use it while I believe the majority of use cases are addressed by open-weight rivals.
I really don’t want to bash Jev. Instead I want to use it as an example of where we are, as an industry.
Incremental improvements
I was one of the lucky few who got access to GPT-2 when it was invitation-only.
As a senior tech lead, I allocate part of my time to scout new tech and experiment in order to stay relevant. Prior to that, I had experienced IBM Watson and a bunch of other products so it wasn’t a big deal for me personally.
I was actually underwhelmed by GPT-2 because at the time it could:
- Summarize text
- Predict what comes after a piece of text
- … that was it really! 😄 I don’t remember more than that. So I moved on…
Then I saw someone create a turn-based dialogue from one of these models and to spice it up, they added an avatar to it. I thought it was creepy and funny.
Then Blake Lemoine came out claiming Google’s language model named LaMDA was conscious. Unsurprisingly, this started a philosophical discussion that’s still ongoing on the side. Again, I didn’t give it too much thought.
BUT, Sam Altman, having spent a few years at the startup accelerator (Y Combinator), saw an opportunity. Specifically the chat application seems to have got his attention and soon ChatGPT was announced.
At the time, I thought it was a cool way to turn their token prediction model into a user-friendly product for the masses.
Personally, I couldn’t use it seriously because:
- Poor quality: it didn’t know what it didn’t know, so it just winged it (AKA hallucination). Although the rise of “prompt engineering” and “reasoning models” promised to reduce this issue.
- Privacy: I had been working with computers for 2+ decades at the time and live by the mantra that “if it’s possible, assume it happened”. Meaning if OpenAI is technically capable of storing my conversation, I cannot trust it enough to share any company IP or private information with it.
I vividly remember the backlash Google got for their multi-modal demo when people realized it wasn’t recorded in real-time! Those were the days when even a small deception would be a conspiracy.
When llama.cpp came out I got a gaming machine with an NVIDIA card (AI machines weren’t a thing back then) to build with AI.
Meanwhile people discovered that language models can generate code It was tedious to copy/paste it so we got the early versions of a harness.
Quickly after, we got “function calls” which allowed the models to do stuff!
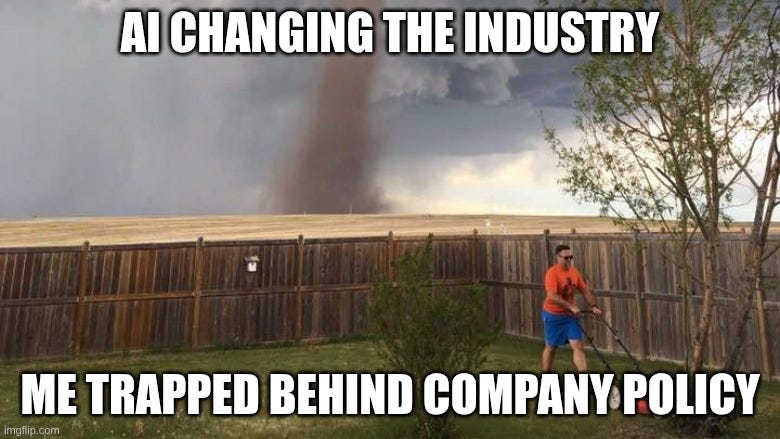
I was using VS Code at the time and the hype was hard to ignore even though my company at the time had a strict policy against using AI tools (yes! hard to believe that just 3-4 years ago companies prioritized IP over velocity).
I remember paying for a Copilot subscription out of pocket and using VS Code insider on my open source projects.
I was so frustrated that I shared this meme on the company Slack:
Meanwhile there was drama at OpenAI (Ilya was part of a coup that fired their CEO, then Satya was playing 4D chess while Elon was lawyering up). It was a sh*tshow which is exactly how it managed to capture the interest of non-techies, a trend that continues to today with “almighty rogue AI” hacking others while whistle-blowers and alarmists rise speak of existential threat!
Simultaneously premature AI products were creating dramas of their own (assisting crimes, cheating, etc.) and AI bros anthropomorphize the tool as if it had desires of its own (my read: they want to judge accountability).
There’s also circular investment, pentagon drama, chip wars, autonomous killer drones, etc. but in the spirit of brevity, let’s stick to the technical side of things.
Then Peter Steinberger, a veteran developer who was away from computers due to burnout, created an AI companion, which brought the Agents (LM that can do stuff) to the mainstream.
So far I’ve covered:
- Instruction-tuned models
- Function calls
- Coding harnesses
- AI agents
Let’s speed through the other incremental improvements:
- Larger parameter size unlocks emergent properties that are hard to explain by analyzing the micro level architecture (mostly leading to sophisticated perceived behavior but also jagged alignment).
- Larger context windows improve accuracy (although the practical limit is much smaller than the theoretical size).
- Multimodal models enable generating voice, music, pictures, and videos while increasingly more models can understand these modalities.
- MCP abstracts away the implementation and enables different AI products to use the tools needed to do productive work.
- ACP, sub-agents and various orchestration techniques allow larger tasks to be planned and broken into smaller pieces.
- Sandboxes help improve security and isolate unwanted side effects of agentic workflows and when they fall short, there’s HITL (but we still haven’t solved the approval fatigue).
- Skills, web search and web access allow agents to access information that’s outside their training data or knowledge cut-off date.
- Various memory architectures and consolidation techniques enable the models to recall what they learn.
- Chinese labs showed us more efficient ways to train and run the models.
- Feedback loops and scratchpads improve the model’s perceived quality by running part of the verification closer to the model.
[
AI Fluency Leveling
·
Jan 30
Read full story](https://blog.alexewerlof.com/p/ai-fluency-leveling)
This is good progress, no question about it. But I think a part of the reason AI is a hot topic is all the drama surrounding it:
- Geopolitics: unlike the US economy which is primarily service-based, China is a manufacturing behemoth. Up until DeepSeek discovered that it can manipulate stock and AI investment by diffusing the compute equation, I don’t think China had a solid AI plan. Now they do. Good old American sanctions target their chip import but China (being run by engineers) made huge strides recently both in chip manufacturing but also in model architecture. Meanwhile AI is used in warfare from drones to intelligence (and mass surveillance back home). In the best seller How the mighty falls, Collins lists 5 stages of demise: a) Hubris Born of Success, b) Undisciplined Pursuit of More, c) Denial of Risk and Peril, d) Grasping for Salvation, e) Capitulation to Irrelevance or Death. Those same stages apply to a falling empires and in this case US has bet big on AI while China diffuses US’s massive bet with open-weight models. Consumers win for now.
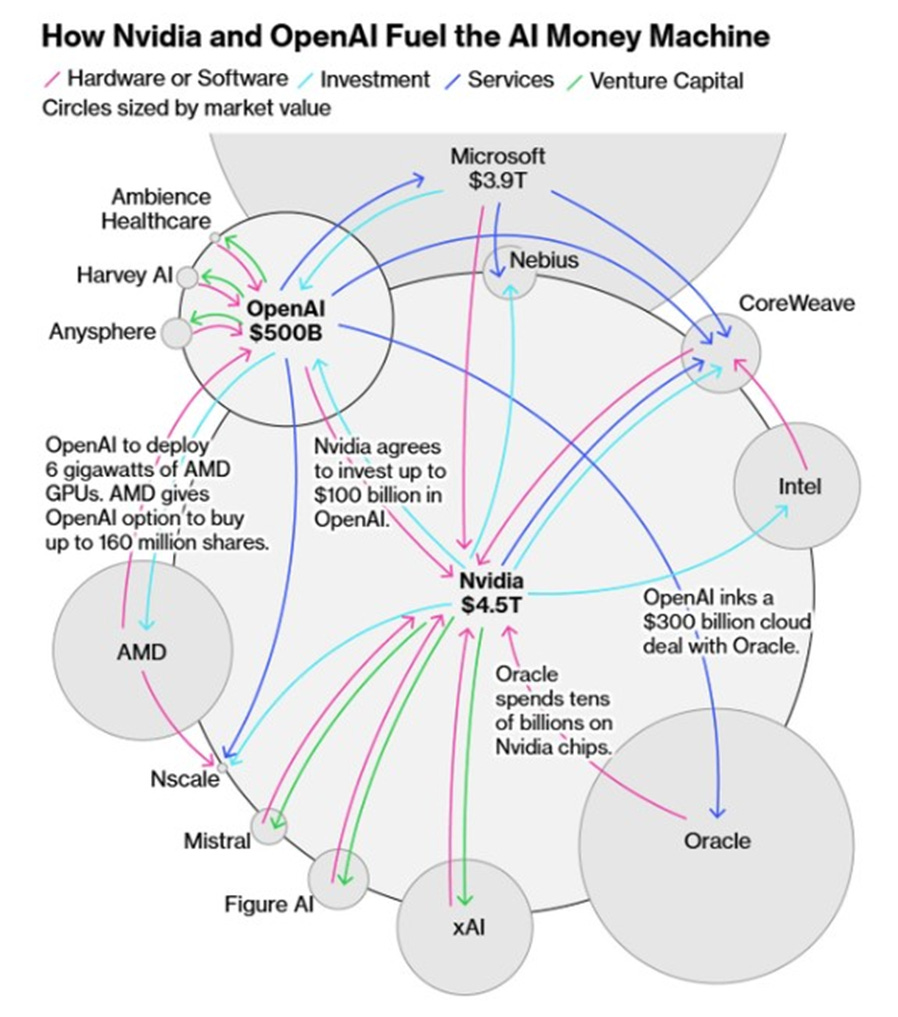
Debt bubble: You can read more on Bloomberg but it basically boils down to a series of interdependent bets that is so large it impacts the national GDP. It has to work regardless of how much IP has to be stolen and how many lies have to be told. The stakes are too high at this point.
- Safety: we got used to the “rogue AI” narrative where the AI vendors aren’t held accountable for breaking into other companies and government institutes. Why would we? It’s an open secret that the training data wasn’t legally obtained anyway (and there are multiple class action lawsuits to prove that). On top of it, there have been multiple cases where people lost their lives due to AI — and I’m not even counting “vibe war”. (yes, I actually put an em-dash there!) 🙃
- Impact on jobs: software engineering is low-hanging fruit for AI automation due to its nature (there’s plenty of training data, and the tools are often on a language model’s home turf). There have been discussions of UBI (universal basic income) and UHI (universal high income) but looking at the benevolence of the billionaires running the show, I don’t buy it at all.
[
Coding is NOT solved
·
Sep 26
Read full story](https://blog.alexewerlof.com/p/coding-is-not-solved)
AI is hot, because it can potentially impact all of us. But we have to remember one simple fact:
Humans are fundamentally flawed when it comes to predicting the future.
Most notoriously, we have difficulty understanding the S-curve (meaning the pace of change is slow at the beginning and end).
And with prominent scientists leaving their lucrative positions to slow down the pace of development, we really cannot be sure about how long it will take for AI to really manifest the changes, if ever.
What’s missing?
With all the incremental improvements of the past few years, we still haven’t solved some fundamental problems.
Here’s a short list of what I consider truly game changing:
- Abstract reasoning: neural networks (not just language models) are prone to making stuff up (hallucination). The state of the industry has improved a lot since hands had 5+ fingers and videos were easy to detect, but the closest we’ve come to a true system 2 is to pair the models with code and still the feedback loops and human intervention are necessary.
- Continuous learning: auxiliary context (e.g. skills, grounding, search and various model architectures) has come a long way but we’re far from the state where the models learn in real time. By extension, the next generation of AI should learn from fewer samples, data and repetitions.
- Embodiment: while there have been great improvements in robotic body form factor, we’re still not at a point where AI is rapid and efficient enough to be put in a robot body and react to the sensory stimuli in real time or expose fine motoric control and navigate the 3D world with enough prevision to take over “simple” human chores.
- Economics of running AI: Jensen Huang talks about installing “Gigawatts” of compute as if it’s normal to measure temperature in kilometers/hour!!! The truth is: our brain delivers AGI level intelligence at 20 Watts and until we solve that problem, there is not enough water, power and data centers that can realistically make massive change in workforce. Unfortunately, we live in a post-truth world where hysteria, personalized propaganda and mass psychosis have an oversized impact on the dominant discourse so we’re all supposed to be scared and distracted. The economics makes even less sense if we expect embodied AI (robots) to replace even a fraction of human population. Unlike bots, our organic bodies return to nature and participate in the nature’s recycling system much faster than metals and plastic that build a robot. Sometimes I feel we forgot that we’re living on a tiny rock with finite resources which get increasingly harder to extract.
All of this, is not to say that AI won’t be used to:
- Robosoldiers and robocops
- Generate new diseases
- Connect mass surveillance to personalized propaganda
- Corporate espionage and mass penetration into computer systems
- etc.
The truth is: you don’t need AGI-level of intelligence to cause destruction. The current generation of AI, paired with harness, tools and skills is plenty capable of causing damage in the wrong hands.
And if you think this is not happening already, I know a guy who gives free ice cream in his basement! 🙃
Closing thoughts
I think Jev is a good example of how great marketing fizzed out in the face of reality.
- Is it useful? Yes.
- Is it relevant? Yes.
- Is it revolutionary? Depends on your cost, quality, speed triangle.
- Is it as big as it was claimed? I hope you have the answer by now.
If I had a magic wand, I would want us all to step back and see the holistic arc of recent events and calm down a little. The red flags are easy to see:
- Name dropping: builds a bridge between the new unknown to the trusted known.
- Jargon: make you feel stupid for not having the context.
- Ambiguity: lets your brain fill in the blanks and if you’re an optimist, you’re at risk of getting overly excited and eventually disappointed
- Big claims: require big evidence. Don’t trust the isolated benchmarks that do not resemble how YOU would actually use it, especially if the benchmark is coming from the same entity that has a conflict of interest.
- Drama: engages human emotion to what would otherwise be a logical technical decision. “All publicity is good publicity”.
Unfortunately, I think that ship might have already sailed and in the age of mass-produced synthetic content and personalized propaganda, maybe we’re too stressed to think straight.
Maybe LLMs are “system two”, after all, if we collectively lose our critical thinking and let our emotions be manipulated with the kind of marketing and manipulation we’ve seen too much lately.