For years we have treated the green tick of a passing suite as a kind of psychological safety — a signal that the logic holds and the world is right. The new data suggests that signal has quietly stopped meaning what we think it means.
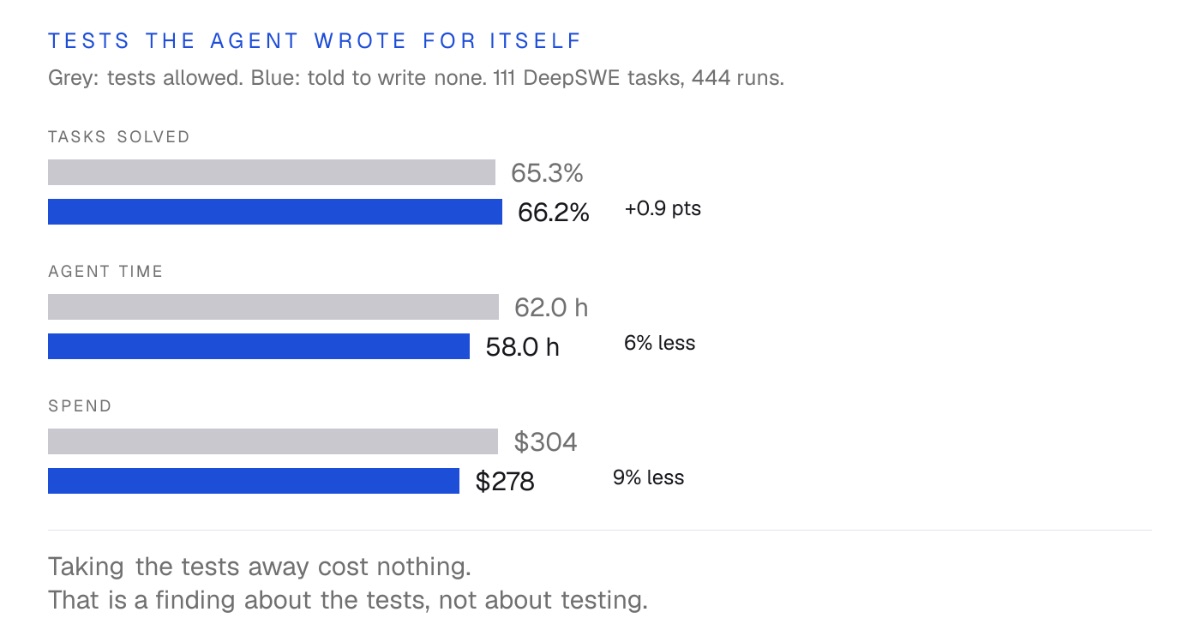
On the DeepSWE v1.1 eval set, Claude Sonnet 5.5 was banned from writing any tests across 111 real-world coding tasks and 444 runs, and compared against a baseline allowed to write as many as it liked.
Taking the tests away cost nothing, and saved something.
The case for taking it seriously
The agent is marking its own homework. The implementation and the tests are both the model's interpretation of your intent, born from the same context window. A test written from the same understanding as the code is not independent evidence about that code. If the understanding was wrong, you get a wrong implementation and a green suite confirming its own error. That is a closed loop, not a check.
It is not a finding about tests. It is a finding about tests nobody asked for — the ones written unprompted, as a reflex, because you requested a change. Bun's rewrite leaned hard on its suite, and that suite was a human asset curated over years to encode intended behaviour. Nothing in this eval touches it. The comparison is tests a human specified against tests a model volunteered.
Stop blaming the codebase. These runs are not on legacy spaghetti. They are on repositories like FastAPI. If the theory is that agents write bad tests because the surrounding code is bad, that theory has to explain FastAPI.
The case against
"Tests are for regressions, and a single-task benchmark cannot see them." The strongest objection, and already answered. The 44-task subset is precisely that experiment, and disabling the suite produced no extra regressions.
"Then tests never worked." Too strong, and the data does not say it. TDD was genuinely useful to humans for years during first-pass development. The finding is narrower and stranger: agents do not appear to inherit the benefit humans got from it. That is worth investigating, not celebrating.
"Mutation testing fixes it." Half right. Mutation testing cannot tell an intended change from an unintended one, so when a test nobody asked for fails, it cannot say whether the code broke the test or the test was wrong. It is not a source of truth. It is still a good eval: break the implementation deliberately and see whether anything notices. A suite that survives deliberate breakage is provably decoration. Use it to delete, not to trust.
"This settles testing." It does not. The agents wrote 17 end-to-end tests against more than 3,000 unit and integration tests. Nothing here says anything about that layer, in either direction.
Where that leaves me
A test is worth exactly what the intent behind it is worth. It is an intermediate representation of something a person decided. When the agent writes both the code and the check, the chain becomes a loop: two artefacts expressing one guess, and a build that goes green when they agree with each other.
For anyone in the trenches with these tools today:
- Stop accepting tests you did not ask for. If the agent volunteered it, it is not evidence.
- Specify the cases yourself where you can express intent better as a test than as a sentence of requirements.
- Run mutation testing to delete , not to trust. Find the dead weight and remove it.
- Read the diff on high-risk paths. The suite was written by the same thing that wrote the code.
And if the cost of being wrong is an afternoon, just code away. Most work does not need the ceremony, and pretending otherwise is how the ceremony got so expensive.
References