In 2022, Google published a way to make language models answer 2 to 3 times faster, with the same answers.[1] Today OpenAI, DeepSeek and Google use it in production.
Engineers serving large language models face three problems:
- A large model takes seconds to answer one question.
- A small model answers fast, but it is less intelligent.
- Agents call the model again and again. Every second adds up.
In this blog we will see what speculative decoding is, and why checking a draft is faster than writing it.
1. A large model is slow
Have you waited for a chatbot to finish its answer? The wait comes from the size of the model.
Imagine you have this really large 300 billion parameter model. When it gets a question from the user, it takes 10 seconds to give a response. That's a lot of time.
That 10 second wait comes from how the model writes. Asked "Please calculate the result of 319 divided by 125", it writes its answer one token at a time. Each token depends on the ones before it.
For every token, the model reads all of its weights. So 300 billion parameters are read once for every word it writes.
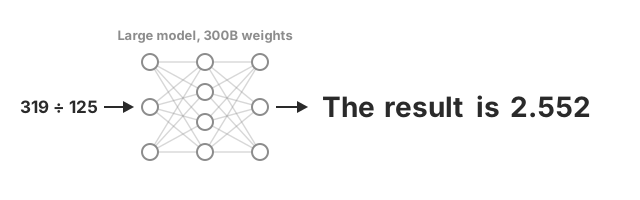
A small neural network, the large model with 300 billion weights, takes the question 319 divided by 125. For each word its neurons fire layer by layer, left to right, and the word comes out into the answer, which grows one word at a time: The, The result, The result is, The result is 2.552.
2. Using SLMs
How do you speed up these models? The first answer most engineers try is a small language model, or SLM.
One idea is to just use a small model. But a smaller model is less intelligent, and isn't as useful.
The SLM has fewer weights to read. Its steps are quick. It answers "The result of this is 2.689".
The large model answers "The result of this is 2.552". And 319 divided by 125 is 2.552.
So a small model alone has the speed, and a large model has the intelligence.
3. Speculative decoding
Can one system have both? It can, if the small model writes and the large model checks.
How do we get the speed of a small model and the intelligence of a large model together? The idea is speculative decoding.
The term speculative means that the small model actually tries to generate answers which are fast but potentially inaccurate. And the large language model does one thing: verify whether the small language model's answers are correct or not.
So what we could do is take every result of the small language model, and pass it into the large language model. The first prefix is "The", the second is "The result", the third is "The result of", and so on.
You send all of these to the large language model, and it computes them in parallel, in batch.
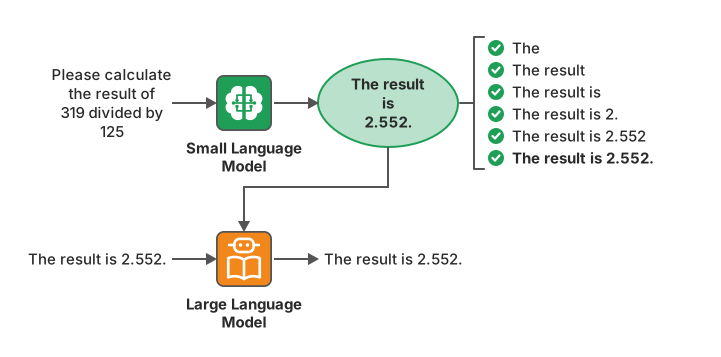
The prompt, 319 divided by 125, goes to the small language model, which drafts The result of this is 2.689. The draft is split into prefixes, and all of them go to the large language model. It ticks The and The result, crosses The result of, and sends back change to The result is. The next draft, The result is 2.8, is ticked up to The result is 2. and corrected to The result is 2.552. Last, every prefix of The result is 2.552. is ticked.
The large language model looks at the first sequence, "The". That matches. The second, "The result", matches too.
The third sequence is "The result of". Here the large language model may come up with a shorter answer: "The result is". So there is a mismatch. Instead of "of", it came up with "is".
The large language model tells the small language model that there's a mistake here, and changes the sentence to "The result is". The small language model now has to predict the next tokens.
Let's say it comes up with an answer of 2.8. The large language model takes both sequences in parallel, and sees that "2." is correct, but "2.8" is incorrect. It changes it to 2.552.
The small language model says this seems correct, and ends the sentence with a full stop. The large language model looks at the full stop, and says that looks fine.
So the answer sent is still the large model's own. Google's post says the output has "exactly the same probability distribution" as the large model's own decoding.[1]
4. Why checking is faster than writing
Isn't this double work? The small model writes every word, and the large model still checks every word.
Most words for a large language model can be predicted with high accuracy and very little thought, but some words require a lot of effort.
Which of these tokens do you think required the most time? "The" is easy. "Result" is easy. It's only at the end where all the thought has to come in, where all the parameters of the model work together.
Even here, "2." is much easier to guess than the "552" after it. So the effort required to generate these tokens is not equal.
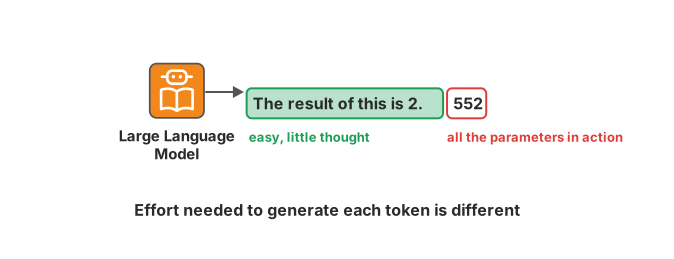
The large language model answers The result of this is 2.552. The words The result of this is 2. are marked green, easy, little thought. 552 is marked red, all the parameters in action. Under it: effort needed to generate each token is different.
The easy words are the small model's job. And its cost hardly counts.
The small language model has around a thousand times fewer parameters than the large language model. Any output from the SLM can be ignored in terms of cost.
The thing to focus on is the large language model. All the sequences in the large language model run in parallel, so it comes up with the results together.
Done the naive way, every output would have to go back to the large language model, one after the other. You have effectively made it a verifier.
The small model's cost is small in Google's tests too. T5-XXL, with 11 billion parameters, ran about 3 times faster with the 60 million parameter T5-small drafting.
5. Who uses it?
Is 3 times faster only a test result? No, it's serving live traffic today.
This ingenious idea is being used by OpenAI, DeepSeek and Claude to speed up responses.
DeepSeek's DSpark framework is deployed in the DeepSeek-V4 serving system, under live user traffic.[2] It made generation 60% to 85% faster for each user, against DeepSeek's earlier production baseline.
Google uses it in Search. Its post says speculative decoding lets AI Overviews produce results faster, at the same quality.
Summary
- A large model writes one token at a time, and reads all of its weights for every token.
- A small language model (SLM) is fast, but less intelligent.
- In speculative decoding, the small model drafts five to ten words, and the large model verifies them.
- Where the draft is wrong, the large model takes its own answer. The output doesn't change.
- Most tokens are easy to predict. The large model checks a draft's prefixes in parallel, where writing them is one step per word.
- Google measured speedups of 2 to 3 times, and DeepSeek-V4 serves its users with it.
Sources
- Looking back at speculative decoding, Yaniv Leviathan and others, Google Research, 6 December 2024.
- DSpark: Confidence-Scheduled Speculative Decoding with Semi-Autoregressive Generation, Xin Cheng and others, arXiv, 6 July 2026.